Welcome
How to Cite This Book
If you use this book in your work, please cite it as:
APA: Chaudhri, A. (2026). Lessons Learned Putting Jev Inside Neo4j. Self-published. https://jev-inside-neo4j.github.io/
BibTeX:
@online{chaudhri2026jevinsideneo4j,
  author  = {Chaudhri, Akmal},
  title   = {Lessons Learned Putting Jev Inside Neo4j},
  year    = {2026},
  url     = {https://jev-inside-neo4j.github.io/},
  urldate = {2026-10-09}
}
Cover
License
Copyright
Copyright © 2026 Akmal Chaudhri. All rights reserved.
Publication Information
First published: October 2026
The latest version of this book, together with updates, errata and additional resources, is available at:
Book License
Lessons Learned Putting Jev Inside Neo4j is licensed under the Creative Commons Attribution-NonCommercial-NoDerivatives 4.0 International License (CC BY-NC-ND 4.0).
You are free to copy and redistribute this book in any medium or format under the following conditions:
- Attribution - You must give appropriate credit, provide a link to the license and indicate if changes were made.
- NonCommercial - You may not use the material for commercial purposes.
- NoDerivatives - If you remix, transform or build upon the material, you may not distribute the modified material.
The full license text is available at:
creativecommons.org/licenses/by-nc-nd/4.0
Code License
Unless otherwise stated, all code samples, notebooks, scripts, data files and source files accompanying this book are licensed under the Apache License 2.0.
You are free to use, modify and redistribute this code, including for commercial purposes, subject to the terms of the Apache License 2.0.
The full license text is available at:
apache.org/licenses/LICENSE-2.0
This distinction means that the book’s written content is protected under the Creative Commons license, while the accompanying code remains freely available for use, modification and integration into your own projects.
Trademarks
Product names, company names and logos mentioned in this book may be trademarks or registered trademarks of their respective owners.
Their inclusion is for identification and educational purposes only and does not imply any affiliation with, sponsorship by or endorsement from the respective trademark holders. All trademarks remain the property of their respective owners.
Disclaimer
The information in this book, including all code samples, scripts and notebooks, is provided “as is” without warranty of any kind, express or implied.
The author makes no representations or warranties regarding the accuracy, completeness, reliability or suitability of the information contained herein for any particular purpose.
Examples are provided solely to illustrate technical concepts, database patterns and software architectures.
Readers are responsible for independently validating all code, configurations and recommendations before using them in production environments.
To the fullest extent permitted by law, the author shall not be liable for any direct, indirect, incidental, special, consequential or other damages arising from the use of or inability to use, the information, code or techniques described in this book.
About the Author
Akmal Chaudhri is a technical leader, educator and author with extensive experience in databases, AI and developer relations. He specializes in technical writing, developer education and community building, helping engineers and organizations understand and adopt complex technologies through clear, practical and engaging content. He is a frequent international speaker, a published author and a contributor to industry discussions on data platforms, AI and software development.
Today, Akmal works in developer education at Neo4j, where he focuses on technical content, workshops and community initiatives. While his professional role has evolved, this book represents an independent exploration of Neo4j.
Based in the United Kingdom, Akmal continues to work at the intersection of databases, AI and developer tooling, helping developers build modern data-driven applications.
For book updates, code samples and additional resources, visit the Book website.
To connect professionally or follow his latest work, visit LinkedIn.
Introduction
What This Book Is
This book follows the building of a small piece of software: a function and a batch procedure for Neo4j, written in Java, that ask a model to make a decision about a node and store the answer back in the graph. We build it one lesson at a time and each lesson comes from a problem we hit or a number we measured.
We don’t start from a design and apply it. Each chapter adds the code that the previous chapter’s problem called for. A first version fails the whole query when a call fails, so we change it. A configurable address would send a credential to the wrong place, so we add a rule. By the end you’ll have seen the function grow from a single call into something you could put in front of a whole graph and you’ll know why each part is there.
One example runs through every chapter: 500 synthetic transactions, a question about each one and the decisions stored as nodes linked to the transactions they describe. It’s small enough to run on a laptop and varied enough to show where a decision is easy and where it isn’t.
What It Isn’t
It isn’t a study of how good any model is. We run a hosted service and a small local model (tev1:0.8b, served by Ollama) on the same data and we report what happened, but the data are synthetic, the runs are few and the prompt is one we wrote once. The numbers show how the code behaves and give a sense of scale. They aren’t a ranking.
It isn’t a product manual either. The code is there to teach, so it favors being easy to read over being complete and the book says what it leaves out.
How to Read It
Read the chapters in order. Each builds on the one before and each uses only what has been built so far, so nothing in a chapter depends on code you haven’t seen.
Every chapter that has code has a folder in the repository, with the project as it stands at the end of that chapter. The folders build on their own, so you can start from any of them if you’d rather not follow every step. The JAR has the same name in every folder, which means a newer one simply replaces the older one.
When a chapter gives Cypher to run, run the statements one at a time. Running a whole file at once only tells you that it succeeded and the point of most of the statements is the result they show you. Each Cypher script also comes as a notebook, with one statement per cell, so you can use whichever you prefer.
The output you see in the book is real output from our runs, pasted in. Where a number came from a run that we didn’t repeat, the chapter says so. Where something surprised us and we don’t know why, the chapter says that too.
Conventions
We write about the graph in graph terms: nodes and relationships, which some people call edges. A query returns results and where we need a count of what came back, we count those results. The word “row” appears only where we mean one line of a query’s output or a line in a CSV file.
We write “we” for the build, because the code and the measurements came out of working through it. Versions of tools and libraries are pinned in the code files and the pom and left out of the text, so the text doesn’t go stale when the code is updated.
Where to Start
Chapter 1 explains why a decision belongs in the database, shows what the finished function returns and tells you what you need to follow along. If you already know that and want to see code, chapter 2 builds the first working function and makes the first call.
Chapter 1: Why Decisions Belong in the Database
The Problem
A graph is good at questions about structure: who is connected to whom, how far apart two nodes are, which paths loop back on themselves. It isn’t good at questions of judgment. Is this transaction suspicious? Does this support ticket sound urgent? Is this review about shipping or about the product? Questions like these have no Cypher pattern, because the answer isn’t in the shape of the graph. It’s in the meaning of the properties.
Today the usual route to an answer looks like this:
Neo4j -> export -> script -> model -> script -> import -> Neo4j
It works, but it has costs that show up every time:
- The data leaves the database. Every export is a copy and every copy needs somewhere to live and someone to look after it.
- The glue code is yours. Retries, timeouts, rate limits and bad responses get solved again in every project, usually the second time something breaks.
- The answers arrive detached. They come back as a file and have to be matched to the right nodes before they’re any use.
- The decision isn’t part of the query. You can’t ask a question about your graph and have a model’s judgment as one step in the middle of it.
The last cost matters most. If a decision were just another step in a Cypher statement, we could filter on it, group by it and traverse from it, like any other property.
The Idea
We make the decision a function. You call it from Cypher the way you’d call any built-in function and it returns an answer:
jev.decide(state, questions [, options])
The three arguments are simple:
statedescribes the thing to decide about. In our case it’s a map of a node’s properties.questionssays what to decide. A choice question picks one option from a set of labeled options. A score question rates the state against an ordered list of levels.optionsis optional and sets things like the model, the endpoint and the timeouts.
The function returns one map with three parts: the answers (with a probability for each option of a choice question), an error_message and some metadata about the call.
One design decision shapes the whole book: the function never throws. If the service is down, the key is missing or the question is malformed, you get an error_message and no answers and the query carries on. We come back to this in chapter 3.
A second piece, jev.decideAll, is a procedure that takes many states and returns one result per state. It’s what turns the function from a convenient call into something that can work through a whole graph and chapter 6 is about it.
The service behind the function is Jev, which takes a state and a set of questions and returns an answer with probabilities. The function speaks a simple HTTP API, so the same call can also go to a local model server. We use that in chapter 7.
The Use Case
Our running example is a small one. We have a set of Transaction nodes and for each one we want to answer a single question: should this transaction be flagged for review or passed through?
The function returns a decision with probabilities attached. We store each decision as a Decision node linked to its transaction. After that, everything we want to know is a query: which flagged transactions was Jev least sure about, which passes might be missed fraud, how much of the graph can be handled without a person looking at it.
We build this example up one piece at a time. Each chapter adds a part of the code and uses only what’s been built so far, so there’s something working from chapter 2 onward and nothing the reader has to take on trust.
The Data
The dataset is 500 synthetic transactions generated with a fixed random seed, so everyone works with the same ones. Each Transaction node has eight properties that the function gets to see:
amountmerchant_categorydistance_from_home_kmhour_of_dayaccount_age_daysprior_flagstxns_last_24htypical_monthly_spend
Each node also carries three properties that the function never sees: scenario, true_p and is_fraud. These are the generator’s answers. They’re stored with the data so we can check the decisions later and they never become part of a request.
The transactions come from scenarios such as routine spending, a traveler far from home, a late-night cash withdrawal and a card being tested with tiny purchases. Each scenario has a latent probability of fraud and the label is drawn from it. A routine purchase is almost never fraud and a clear case of fraud almost always is, while a late-night withdrawal sits in the middle. This is deliberate. A real judge has to live with cases that are genuinely ambiguous and so does ours.
The graph model for the example is:
(:Transaction {txn_id, amount, merchant_category, distance_from_home_km,
               hour_of_day, account_age_days, prior_flags, txns_last_24h,
               typical_monthly_spend, scenario, true_p, is_fraud})
  -[:HAS_DECISION]->
(:Decision {choice, confidence, p_flag, p_pass,
            latency_ms, attempts, model})
Chapter 6 creates the Decision nodes, when we store the results of a full run.
A Preview of the Result
Here’s where we’re heading. There’s nothing to run yet. This is the call we’ll make in chapter 2, on one transaction:
RETURN jev.decide(
  {
    amount: 2992.06,
    merchant_category: 'travel',
    distance_from_home_km: 8.1,
    hour_of_day: 14,
    account_age_days: 1483,
    prior_flags: 0,
    txns_last_24h: 2,
    typical_monthly_spend: 3230
  },
  {
    decision: {
      type: 'choice',
      instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
      criteria: {
        Flag: 'Potential fraud. Send for review.',
        Pass: 'Likely legitimate. Process normally.'
      }
    }
  }
) AS result
And this is the result, from a real run:
{
  answers: {
    decision: {
      type: "choice",
      choice: "Pass",
      probabilities: {
        Pass: 0.91,
        Flag: 0.09
      },
      confidence: 0.82
    }
  },
  error_message: null,
  metadata: {
    model: "jev-latest",
    latency_ms: 349
  }
}
Jev passed the transaction, with 91% of the probability on Pass and 9% on Flag. We unpack the other fields in chapter 2.
Once the decisions are stored, a question that used to need an export and a script is a single query:
MATCH (t:Transaction)-[:HAS_DECISION]->(d:Decision)
WHERE d.choice = 'Flag'
RETURN t.txn_id, t.amount, d.p_flag
ORDER BY d.p_flag ASC
LIMIT 5
This lists the five flagged transactions the decision was least sure about, which is where a person should look first. The property names are the ones chapter 6 creates.
The Companion Repository
Everything in this book lives in one repository: the text of each chapter, the code and the data. You can find it at:
github.com/jev-inside-neo4j/jev-inside-neo4j.github.io.
jev-inside-neo4j.github.io/
  src/part-main/                  the text of each chapter
  code/
    data/                         transactions.csv
    02-first-working-function/    the project as it stands at the end of chapter 2
    03-.../                       and one folder for each chapter after that
Each chapter that has code gets a folder in code with the same name as the chapter. Every folder is a complete project that builds on its own, so you can start from any chapter. The JAR has the same name in every folder, which means a newer one simply replaces the older one.
Cloning the repository, building a chapter and running the notebooks are covered in “Setting Up” at the end of this chapter. A table of every file you can run is in “What’s in the Repository”, right after it.
What the Book Builds
Each chapter takes one lesson from the build and adds the code that goes with it:
- Chapter 2, A First Working Function. The project setup, how Neo4j treats the types that cross the boundary and the first live call.
- Chapter 3, Failures as Data. Why the function returns an error instead of throwing and the categories of error it can return.
- Chapter 4, Testing Without a Network. A fake transport, retry and backoff tests and live notebooks as a second layer.
- Chapter 5, Keeping the Key Safe. A leak we found while testing and the rule that closed it.
- Chapter 6, Many at Once. The batch procedure, a bounded thread pool and what the timings show.
- Chapter 7, Running It Locally. The same function against a local model and what changes.
What You’ll Need
- Neo4j Desktop. The function is a plugin, so it runs in a local database. Download from Neo4j for Desktop.
- A Java development kit and Maven. We build the plugin ourselves.
- A Jev API key. Chapter 5 shows how the function reads it and where it sends it.
- Git or GitHub Desktop. To clone the book’s repository.
- Optionally, Ollama. Chapter 7 uses it to run a small model on your own machine.
The versions of every tool and library are pinned in the code files that come with the book.
Setting Up
This section takes you from nothing to a working function. Chapter 2 walks through the same steps again with the reasons behind them, so here we keep to the commands. Where a step runs Cypher, run the statements one at a time. A whole script at once only tells you that it succeeded and most of the statements are there for the result they show.
1. Get the repository. On the command line:
git clone https://github.com/jev-inside-neo4j/jev-inside-neo4j.github.io.git
cd jev-inside-neo4j.github.io
In GitHub Desktop, choose File, then Clone Repository, open the URL tab, paste https://github.com/jev-inside-neo4j/jev-inside-neo4j.github.io, pick a folder on your machine and click Clone. Either way you end up with a folder named jev-inside-neo4j.github.io. All paths in this book are relative to it.
2. Check Java and Maven. Both commands should print a version and not an error:
java -version
mvn -version
If either one fails, install it first. The versions the project needs are set in each chapter’s pom.xml.
3. Build a chapter. Each chapter’s folder is a complete project. To build chapter 2:
cd code/02-first-working-function
mvn clean package
The JAR appears in the folder’s target directory as neo4j-jev-decide-1.0.0.jar. From chapter 4 on, the folders also have unit tests. Run them on their own with:
mvn test
The tests use a fake transport, so they need no network and no key. mvn clean package runs them too.
4. Install the plugin. In Neo4j Desktop:
- Stop the database.
- On the instances page, click the Open Folder button next to the database. It shows the folders Desktop uses, such as
config,importandplugins. Copy the JAR into thepluginsfolder. - Open the configuration file,
neo4j.conf, in theconfigfolder and add these two lines, with your own key in place of the placeholder:
dbms.security.procedures.allowlist=jev.*
server.jvm.additional=-DTYPESAFE_API_KEY=your-api-key
- Start the database and check that the function is registered:
SHOW FUNCTIONS YIELD name WHERE name STARTS WITH 'jev' RETURN name
You should see jev.decide. From chapter 6 on, you’ll also see jev.decideAll under SHOW PROCEDURES. Don’t commit the key anywhere. It stays in neo4j.conf and nowhere else.
Each chapter’s JAR has the same name, so moving to another chapter means stopping the database, replacing the JAR in plugins with the new one and starting the database again. Only one chapter’s JAR can be installed at a time.
5. Load the data. Copy code/data/transactions.csv into the database’s import folder. You’ll find it with plugins and the other folders behind the Open Folder button. The chapter 2 notebook 02_load_and_call.ipynb, loads the file and makes the first call. Run it before any later chapter, because every later chapter uses the 500 transactions it creates.
6. Set up the notebooks. The notebooks run in Jupyter and connect to your database over Bolt. Create a virtual environment, activate it and install Jupyter in it:
python3 -m venv myenv
source myenv/bin/activate
Then set the connection details in the same terminal, before you launch Jupyter, because the notebooks read them from the environment:
export NEO4J_URI="bolt://localhost:7687"
export NEO4J_USERNAME="neo4j"
export NEO4J_PASSWORD="your-password"
export NEO4J_DATABASE="neo4j"
On Windows, use set in place of export and myenv\Scripts\activate in place of source. Each notebook installs the exact versions of the two libraries it needs in its first code cell, so there is nothing else to install. The notebooks never see your API key. The database reads it from neo4j.conf.
7. Optionally, set up Ollama. Chapter 7 is the only chapter that uses it. Install Ollama, then pull the model once:
ollama pull tev1:0.8b
Leave Ollama running while you work through chapter 7.
If something doesn’t work
SHOW FUNCTIONSdoesn’t listjev.decide. The JAR isn’t inplugins, the allowlist line is missing fromneo4j.confor you didn’t restart the database after changing either one.- A call returns
no_api_key. Theserver.jvm.additionalline is missing or misspelled. Check it and restart the database. - A chapter’s notebook fails on something the chapter introduced. You may have an earlier chapter’s JAR installed. Install the JAR from the chapter you’re reading and restart.
- A chapter 7 call returns an
ioerror naminglocalhost:11434. Ollama isn’t running. - A notebook can’t connect. The environment variables were set after Jupyter started. Stop Jupyter, set them and start it again from the same terminal.
What’s in the Repository
Every file you run is in a chapter’s folder under code, apart from the data file. The .cypher files hold the statements the chapter shows. The notebooks run the same statements one per cell and show each result. Run the statements one at a time, in order. The test notebooks check the function against the real services and save what they found in a JSON file next to them.
| File | Chapter | What it does | Needs |
|---|---|---|---|
code/data/transactions.csv | 2 | The 500 synthetic transactions | Copied into the import folder |
load-and-call.cypher | 2 | Loads the transactions and makes the first call | Plugin |
notebooks/02_load_and_call.ipynb | 2 | The same statements, one per cell | Plugin, Jupyter |
failure-demos.cypher | 3 | Triggers each kind of failure and shows the error | Plugin, data loaded |
notebooks/03_failure_demos.ipynb | 3 | The same statements, one per cell | Plugin, data loaded, Jupyter |
notebooks/04_decide_tests.ipynb | 4 | Live tests of jev.decide, including retries and timings | Plugin, key, Jupyter |
notebooks/results_decide.json | 4 | Saved results of the last run | Written by the notebook |
key-demos.cypher | 5 | Shows where the key is sent and where it isn’t | Plugin, key |
notebooks/05_key_demos.ipynb | 5 | The same statements, one per cell | Plugin, key, Jupyter |
notebooks/05_decide_tests.ipynb | 5 | Live tests, now including the key rules | Plugin, key, Jupyter |
notebooks/results_decide.json | 5 | Saved results of the last run | Written by the notebook |
run-all-500.cypher | 6 | Decides all 500 transactions with jev.decideAll and stores Decision nodes | Plugin, key, data loaded |
notebooks/06_run_all_500.ipynb | 6 | The same statements, one per cell | Plugin, key, data loaded, Jupyter |
notebooks/06_decideall_tests.ipynb | 6 | Live tests of the batch procedure and the concurrency sweep | Plugin, key, Jupyter |
notebooks/results_decideall.json | 6 | Saved results of the last run | Written by the notebook |
run-local-500.cypher | 7 | Decides all 500 transactions with the local model and stores LocalDecision nodes | Plugin, Ollama, the chapter 6 decisions |
notebooks/07_run_local_500.ipynb | 7 | The same statements, one per cell | Plugin, Ollama, the chapter 6 decisions, Jupyter |
notebooks/07_decide_tests.ipynb | 7 | Live tests against Jev and the local model | Plugin, key, Ollama, Jupyter |
notebooks/07_decideall_tests.ipynb | 7 | Live batch tests against Jev and the local model, with the local sweep | Plugin, key, Ollama, Jupyter |
notebooks/results_decide.json and notebooks/results_decideall.json | 7 | Saved results of the last runs | Written by the notebooks |
The results files are overwritten each time you run their notebook. The Java source is in each folder’s src directory and the chapters explain it as it grows.
In the next chapter we build the first version of the function and make the call from the preview on a real transaction.
Chapter 2: A First Working Function
What Is It?
Neo4j lets you add your own functions to Cypher. You write a Java class, mark a method with @UserFunction, package it as a JAR and drop it in the database’s plugins folder. After a restart, your function sits next to the built-in ones and you call it the same way.
Our function is jev.decide. This chapter builds the smallest version that works: one call, one transaction, one answer. It has no retries, no validation and no clever error handling. Those come later and each one arrives because something went wrong without it.
A user-defined function has three parts:
- A name. The
@UserFunctionannotation gives it, herejev.decide. The part before the dot is a namespace, which keeps our function from colliding with anything else. - Parameters. Each one is marked with
@Name. A parameter can have a default, which is how the third argument becomes optional. - A return value. Whatever the method returns, Neo4j hands back to Cypher.
The types at the boundary follow a fixed mapping:
| Cypher | Java |
|---|---|
| Integer | Long |
| Float | Double |
| String | String |
| Boolean | Boolean |
| List | List |
| Map | Map |
| null | null |
A parameter declared as Object accepts any of these, which is how our state argument can be either text or a map.
The Project
The project is small. Five files and a pom. You’ll find them in the code folder of the book’s repository:
code/02-first-working-function/
  pom.xml
  load-and-call.cypher
  notebooks/02_load_and_call.ipynb   the same statements, one per cell
  src/main/java/com/example/jevdecide/
    JevDecide.java          the function Neo4j sees
    JevClient.java          builds the request and reads the response
    HttpTransport.java      the one thing the client needs from the network
    JdkHttpTransport.java   the real transport, built on Java's own HTTP client
    TypeNormalizer.java     moves values between Cypher's types and JSON's
The pom needs two decisions.
First, Neo4j itself is a provided dependency. The database supplies its own API when it loads our JAR, so we compile against it and leave it out of the package.
Second, we bring our own JSON library, Jackson, and relocate it. Neo4j carries its own copy of Jackson and two copies of the same library on one class path is a recipe for strange failures. The Maven shade plugin moves our copy into a package of our own, so the two never meet:
<relocations>
  <relocation>
    <pattern>com.fasterxml.jackson</pattern>
    <shadedPattern>com.example.jevdecide.shaded.jackson</shadedPattern>
  </relocation>
</relocations>
The shade plugin also needs to leave Neo4j’s classes out of the finished JAR:
<artifactSet>
  <excludes>
    <exclude>org.neo4j:*</exclude>
  </excludes>
</artifactSet>
The versions of the tools and libraries are pinned in the pom, not in this text.
JevDecide is deliberately thin. Neo4j sees this class and everything it does is hand the arguments to JevClient:
@UserFunction("jev.decide")
@Description("Ask Jev typed questions about a state. Returns {answers, error_message, metadata}. "
        + "In this first version a failure raises an error.")
public Map<String, Object> decide(
        @Name("state") Object state,
        @Name("questions") Map<String, Object> questions,
        @Name(value = "options", defaultValue = "{}") Map<String, Object> options) {
    return CLIENT.decide(state, questions, options);
}
Keeping the logic out of this class matters. Anything that needs a running Neo4j to test is slow to test. Anything in JevClient doesn’t and chapter 4 takes advantage of that.
The Type Rules
The obvious way to build the result is to return the answers exactly as Jackson parsed them. That doesn’t work and the reason is in the mapping table above.
Neo4j accepts Long for integers and nothing smaller. Jackson, given a small whole number in JSON, produces an Integer. A probability such as 0.93 is fine, because it becomes a Double. But a whole number in the response, such as a score of 1, arrives as an Integer and that’s a type Neo4j won’t take back.
TypeNormalizer solves it in both directions. On the way back it widens everything to the types Neo4j accepts:
public static Object fromJson(Object value) {
    if (value == null || value instanceof String || value instanceof Boolean
            || value instanceof Long || value instanceof Double) {
        return value;
    }
    if (value instanceof Integer || value instanceof Short || value instanceof Byte) {
        return ((Number) value).longValue();
    }
    if (value instanceof Float) {
        return ((Number) value).doubleValue();
    }
    // ... BigInteger, BigDecimal, Map and Collection are handled the same way
    return String.valueOf(value);
}
On the way out it does the opposite job. It checks what Cypher handed us and rejects anything JSON can’t carry:
if (value instanceof Double || value instanceof Float) {
    double d = number.doubleValue();
    if (Double.isNaN(d) || Double.isInfinite(d)) {
        throw new IllegalArgumentException(path + ": NaN and infinity can't be sent as JSON");
    }
}
The path in that message is the location of the bad value, such as $.amount, so the error says where to look. A map whose keys aren’t text is rejected the same way and so is a type we don’t recognize.
The Request
The API takes three things: a model name, a state and a set of questions.
The state is text. If we’re given text, we send it as it is. If we’re given a map or a list, we serialize it and we sort the keys first:
private String stateText(Object state) throws JsonProcessingException {
    if (state instanceof String text) {
        return text;
    }
    return mapper.writeValueAsString(TypeNormalizer.toJson(state, true));
}
Sorting means the same properties always produce the same request, whatever order Cypher happened to hand them over in. That matters for anything we want to compare later.
For our first transaction the request body looks like this:
{
  "model": "jev-latest",
  "state": "{\"account_age_days\":1483,\"amount\":2992.06,\"distance_from_home_km\":8.1,\"hour_of_day\":14,\"merchant_category\":\"travel\",\"prior_flags\":0,\"txns_last_24h\":2,\"typical_monthly_spend\":3230}",
  "questions": {
    "decision": {
      "type": "choice",
      "instructions": "Based on all available signals, should this transaction be flagged for review or passed through?",
      "criteria": {
        "Flag": "Potential fraud. Send for review.",
        "Pass": "Likely legitimate. Process normally."
      }
    }
  }
}
A choice question takes its options as a map of label to description. A score question takes its levels as an ordered list and mixing the two shapes is an error the API rejects. We don’t check for that yet. Chapter 3 does.
Sending the request is the job of HttpTransport, an interface with a single method:
public interface HttpTransport {

    record Response(int status, String body) {}

    Response post(URI uri,
                  Map<String, String> headers,
                  String body,
                  Duration connectTimeout,
                  Duration requestTimeout) throws IOException, InterruptedException;
}
The real implementation, JdkHttpTransport, uses the HTTP client that ships with Java, so there’s nothing extra to install. The reason for the interface is that JevClient never touches the network directly. It asks an HttpTransport to do it. That’s the seam chapter 4 uses to test the client without a network at all.
The heart of JevClient is short enough to read in one go:
String body = mapper.writeValueAsString(requestBody(state, questions, model));
HttpTransport.Response response =
        transport.post(ENDPOINT, headers, body, CONNECT_TIMEOUT, REQUEST_TIMEOUT);

if (response.status() != 200) {
    throw new IllegalStateException("Jev returned HTTP " + response.status() + ": " + response.body());
}

Map<String, Object> root =
        mapper.readValue(response.body(), new TypeReference<Map<String, Object>>() { });
Object answers = root == null ? null : root.get("answers");
if (!(answers instanceof Map)) {
    throw new IllegalStateException("the response has no answers object");
}
return result(TypeNormalizer.fromJson(answers), model, started);
Build the request, send it, check the status, pull out the answers and normalize them. The result is a map with the answers, an error_message (always empty in this version) and some metadata.
The only option this version reads is model. If you don’t give one, it uses jev-latest.
The Data Goes In
Before the first call we need something to decide about. The repository you cloned in chapter 1 includes a file, code/data/transactions.csv, with 500 transactions. Copy that file into the import folder of your Neo4j Desktop database. Desktop has an option to open a database’s folders and the import folder is one of them.
Then load it:
CREATE CONSTRAINT txn_id IF NOT EXISTS
FOR (t:Transaction) REQUIRE t.txn_id IS UNIQUE;

LOAD CSV WITH HEADERS FROM 'file:///transactions.csv' AS row
MERGE (t:Transaction {txn_id: row.txn_id})
SET t.amount                = toFloat(row.amount),
    t.merchant_category     = row.merchant_category,
    t.distance_from_home_km = toFloat(row.distance_from_home_km),
    t.hour_of_day           = toInteger(row.hour_of_day),
    t.account_age_days      = toInteger(row.account_age_days),
    t.prior_flags           = toInteger(row.prior_flags),
    t.txns_last_24h         = toInteger(row.txns_last_24h),
    t.typical_monthly_spend = toInteger(row.typical_monthly_spend),
    t.scenario              = row.scenario,
    t.true_p                = toFloat(row.true_p),
    t.is_fraud              = toInteger(row.is_fraud);
A CSV file is all text, so every value has to be converted. The conversions aren’t arbitrary. The state goes to Jev as text, so a whole number should stay a whole number and a decimal should stay a decimal. hour_of_day is 14, not 14.0.
The MERGE on the constraint means you can run this twice and still have 500 nodes.
The First Call
Install the JAR and tell Neo4j about it:
- Build the project with Maven by running
mvn clean packageincode/02-first-working-function. The JAR appears in the project’stargetfolder. - Copy the JAR into the database’s
pluginsfolder. - In the database’s config settings file
neo4j.conf, allow the new function withdbms.security.procedures.allowlist=jev.*. - In the same settings, give the database your API key as a JVM option:
server.jvm.additional=-DTYPESAFE_API_KEY=your-key. - Restart the database.
Now the call. The map projection t {.amount, ...} picks out the eight visible properties and nothing else, so scenario, true_p and is_fraud never reach Jev:
MATCH (t:Transaction {txn_id: 'T0001'})
RETURN jev.decide(
  t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
     .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend},
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {
       Flag: 'Potential fraud. Send for review.',
       Pass: 'Likely legitimate. Process normally.'
     }
  }}
) AS result
This is what came back:
{
  answers: {
    decision: {
      type: "choice",
      choice: "Pass",
      probabilities: {
        Pass: 0.91,
        Flag: 0.09
      },
      confidence: 0.82
    }
  },
  error_message: null,
  metadata: {
    model: "jev-latest",
    latency_ms: 349
  }
}
Reading it from the top:
choiceis the option Jev picked. Here it passed the transaction.probabilitiessays how likely Jev thinks each option is. They add up to 1.confidenceis the gap between the two probabilities: 0.91 minus 0.09 is 0.82. A gap of 0 would be a coin flip and a gap of 1 would be certainty. It isn’t the probability of being right, which is the 0.91 next toPass.typerepeats the kind of question we asked.error_messageis empty, because the call worked.metadatasays which model answered and how long the call took, 349 milliseconds here. In this first version it has two fields. Chapters 3 and 5 addattemptsandauthenticated.
For the record, the label we hid says T0001 isn’t fraud, so Pass was the right call.
That’s a decision made inside the database. The query took a node, handed its properties to a function and got an answer back as a value. Nothing was exported.
The same statements are also in notebooks/02_load_and_call.ipynb, which runs them one per cell and shows each result.
What You’d Hit in Production
The JAR needs a restart. Neo4j loads plugins when it starts. Copy in a new JAR and nothing changes until you restart the database. Two JARs that both define jev.decide will also clash, so remove the old one first. Every chapter’s JAR has the same name, so copying a new one over the old one replaces it.
The allowlist. Without jev.* in the procedure allowlist, Neo4j refuses to run the function and the failure is easy to mistake for a bug in the code. Check the allowlist first.
The key doesn’t arrive. Neo4j Desktop starts the database for you, so a variable you exported in a terminal may never reach it. A JVM option in the database settings always does. The function looks for an environment variable first and the JVM property second.
A failure fails the whole query. In this version, a bad key, a network error or a timeout raises an error. Run the function over 500 nodes and one failure stops the lot. That’s the lesson of the next chapter.
A typo is silently ignored. Pass {modle: 'x'} as the options and the function won’t complain. It simply uses the default model. The same chapter fixes that too.
Going Further
We have a function that makes one decision and it works as long as everything goes right. In practice a network call fails in many ways: the key’s missing, the service is slow, the response isn’t what we expected. Right now every one of those stops the query. In the next chapter we change what the function does when something goes wrong and the answer is the idea that shapes the rest of the book: a failure is just another value.
Chapter 3: Failures as Data
The Problem with Throwing
The function from chapter 2 works as long as everything goes right. Here’s what happens when something doesn’t. Take four transactions, one of which doesn’t exist and ask for a decision on each:
UNWIND ['T0001', 'T0002', 'BAD', 'T0003'] AS id
OPTIONAL MATCH (t:Transaction {txn_id: id})
RETURN id, jev.decide(
  t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
     .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend},
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {Flag: 'Potential fraud. Send for review.', Pass: 'Likely legitimate. Process normally.'}
  }}
) AS result
The third row has no transaction behind it, so there’s no real state to decide about. With the chapter 2 version, a failure like that raises an error and the whole query fails. You get no answers at all, not even for the transactions that were fine. Scale this to 500 nodes and one bad property, one slow response or one dropped connection throws away everything the query has already paid for.
The cause is a design choice. In Cypher, an error in a function stops the statement. That’s right for a built-in like toInteger, where a bad value is a bug in your query. It’s wrong for a call to a remote service, where failure is a normal event.
The Rule
From this chapter on, jev.decide never throws. Every failure comes back in the result:
{
  answers: null,
  error_message: "validation: state must not be null",
  metadata: { model: "jev-latest", latency_ms: 0, attempts: 0 }
}
The map has the same three parts as before. When the call works, answers is filled and error_message is null. When it doesn’t, answers is null and error_message says why. Either way the query carries on.
That turns failure into data and data are what Cypher is good at. You can count the failures, group them, filter them out or run only the failed ones again.
The Error Prefixes
A message is only useful to a query if the query can tell one kind from another. So every error_message starts with a category, followed by a colon:
| Prefix | Meaning |
|---|---|
validation | The request was wrong and nothing was sent. |
no_api_key | No key was found in the environment or the JVM properties. |
timeout | The service didn’t answer within the time limits. |
io | The connection failed: DNS, a reset, a refused connection. |
http_429 | The service said we’re sending too much. |
http_5xx | The service failed on its side. |
http_4xx | The service rejected the request. |
malformed_response | The service answered, but not with what we expected. |
interrupted | The thread was interrupted while the call was running. |
internal | Something unexpected happened in our own code. |
The prefix is the stable part. The text after it can change, but a query that checks error_message STARTS WITH 'timeout' keeps working. For example, to count a run’s failures by category:
WITH split(result.error_message, ':')[0] AS category
RETURN category, count(*) AS n
Validation Before the Network
The cheapest failure is the one that never leaves the database. Before any request is sent, the function checks three things.
1. The options. The third argument is checked against a short list of known names: model, connect_timeout_ms, request_timeout_ms and max_retries. An unknown name is an error, not something to ignore. In chapter 2 we noted that {modle: 'x'} was silently dropped and the default model used instead. Now it isn’t:
RETURN jev.decide(
  {amount: 120.5, merchant_category: 'grocery'},
  {decision: {
     type: 'choice',
     instructions: 'Should this transaction be flagged or passed?',
     criteria: {Flag: 'Potential fraud.', Pass: 'Likely legitimate.'}
  }},
  {modle: 'jev-latest'}
) AS result
{
  answers: null,
  error_message: "validation: unknown option(s): modle; known options are [connect_timeout_ms, max_retries, model, request_timeout_ms]",
  metadata: {
    model: null,
    latency_ms: 0,
    attempts: 0
  }
}
The message names the bad option and lists the good ones. Note that model is null in the metadata. The options are the first thing read, so when they’re wrong there’s no model to report.
The numeric options have ranges too. Timeouts must be whole numbers and max_retries must be between 0 and 5.
2. The questions. QuestionValidator enforces the shapes from chapter 2. The map must not be empty and each question needs a type and instructions. A choice question needs its criteria as a map of label to description, with between 1 and 255 labels. A score question needs an ordered list of 2 to 10 level descriptions. Mixing the two shapes is the most common mistake and the API answers it with an HTTP 422, so we catch it first:
RETURN jev.decide(
  {amount: 120.5, merchant_category: 'grocery'},
  {decision: {
     type: 'choice',
     instructions: 'Should this transaction be flagged or passed?',
     criteria: ['Flag', 'Pass']
  }}
) AS result
{
  answers: null,
  error_message: "validation: decision: a choice question needs criteria as a map of label to description, not an array",
  metadata: {
    model: "jev-latest",
    latency_ms: 0,
    attempts: 0
  }
}
The message starts with the question’s name, decision, so with several questions you know which one to fix. Question types other than choice and score are checked only for type and instructions. The API decides which other types exist, so we don’t second-guess it.
3. The state. A null state, or text that’s blank, is rejected. So is anything JSON can’t carry, such as NaN or infinity, with the path to the bad value, as in chapter 2:
{
  answers: null,
  error_message: "validation: state must not be blank",
  metadata: { model: "jev-latest", latency_ms: 0, attempts: 0 }
}
All three share two things. latency_ms is 0 and attempts is 0, because nothing touched the network. A validation failure costs nothing and is instant, which matters when the query runs over thousands of nodes.
The Key
The function needs a key to call Jev. If it can’t find one, in the environment variable or the JVM property, it returns a no_api_key error that says where to put it. The key is checked after validation, so a request that’s wrong tells you so even before you’ve set a key up.
Retries and Backoff
Some failures are worth trying again. A timeout may be a busy moment. A 429 means slow down. A 503 is the service having a bad second. Others are not. A 400 or 422 means the request is wrong and sending the same request again gets the same answer.
So the function retries only failures that might pass on their own:
timeoutandio, because the network can recover.http_429andhttp_5xx, because the service can recover.
Everything else, including every other 4xx, fails at once.
Between attempts the function waits and the wait doubles each time: 500 milliseconds before the second attempt, 1,000 before the third:
sleeper.sleep(BACKOFF_MS << (attempt - 1));
Doubling gives a struggling service room to recover instead of hitting it again immediately. The defaults are a 5 second connect timeout, a 15 second request timeout and 2 retries, so up to 3 attempts. You can change any of them in the options. max_retries can be 0 if you’d rather fail fast.
Those defaults have a cost worth knowing about. In the worst case every attempt runs into the request timeout and one call can take close to 47 seconds: three waits of 15 seconds plus the two pauses. For a single call that’s fine. For a thousand calls one after another it isn’t and chapter 6 deals with that.
The sleeper in that line is a small interface:
@FunctionalInterface
public interface Sleeper {
    void sleep(long millis) throws InterruptedException;
}
The real function passes Thread::sleep. The reason for the interface is the same as for HttpTransport in chapter 2. A test that proves the backoff works shouldn’t have to wait for it and in chapter 4 it won’t.
When the retries run out, the message says how many attempts were made. A single attempt reads “(after 1 attempt)” and more reads “(after 3 attempts)”. The attempts field in the metadata carries the same number, so a query can find the calls that needed help.
A Safety Net
Validation and the HTTP handling cover the failures we can predict. The rest is covered by a last catch around the whole call. Any unexpected exception, which in practice means a bug in our own code, becomes an internal error with the exception’s class and message.
This is the part that makes “never throws” true instead of hopeful. Without it, the rule holds only as long as we’ve thought of everything. With it, even a mistake we haven’t found yet arrives as a value in the result and one bad row still can’t take the others down.
There’s one exception to carrying on and it’s deliberate. If the thread is interrupted, the function sets the interrupt flag again and returns an interrupted error. The interrupt is the database asking the work to stop, for instance when someone cancels a query. Swallowing it would make a long call impossible to cancel.
Errors That Say Where
Two small habits make the errors easier to act on. First, they name the host. A timeout reads “no response from api.typesafe.ai within the configured limits” and an I/O failure names the host it was reaching, so you don’t have to guess which service was involved. Second, an HTTP error includes the start of the response body, cut to 300 characters, because the service’s own explanation is often the quickest route to the fix.
Seeing It Work
Here’s the four-transaction query again, with a CASE that makes the missing-node case explicit by passing null as the state. The function rejects a null state as a validation error:
UNWIND ['T0001', 'T0002', 'BAD', 'T0003'] AS id
OPTIONAL MATCH (t:Transaction {txn_id: id})
WITH id, jev.decide(
  CASE WHEN t IS NULL THEN null ELSE
    t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
       .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend} END,
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {
       Flag: 'Potential fraud. Send for review.',
       Pass: 'Likely legitimate. Process normally.'
     }
  }}
) AS result
RETURN id,
       result.answers.decision.choice AS choice,
       result.error_message AS error_message,
       result.metadata.attempts AS attempts
╒═══════╤══════╤════════════════════════════════════╤════════╕
│id     │choice│error_message                       │attempts│
╞═══════╪══════╪════════════════════════════════════╪════════╡
│"T0001"│"Pass"│null                                │1       │
├───────┼──────┼────────────────────────────────────┼────────┤
│"T0002"│"Pass"│null                                │1       │
├───────┼──────┼────────────────────────────────────┼────────┤
│"BAD"  │null  │"validation: state must not be null"│0       │
├───────┼──────┼────────────────────────────────────┼────────┤
│"T0003"│"Pass"│null                                │1       │
└───────┴──────┴────────────────────────────────────┴────────┘
Three transactions got a decision and one got an explanation. The bad row used no attempts and the others used one each. Nothing stopped.
All three validation errors above are failures we can trigger on demand. The network failures are harder to show, because a real timeout or a real 503 isn’t something you can order up. That’s the other reason for the fake transport in the next chapter. It lets us produce any failure we like and check that the function responds the way this chapter says it does.
The statements from this chapter are also in notebooks/03_failure_demos.ipynb, which runs them one per cell and shows each result.
What You’d Hit in Production
The error is a value, so check it. A query that reads result.answers.decision.choice gets null for a failed call, which looks the same as a missing property. If it matters, test error_message IS NULL first, or keep both fields.
Retries add latency. A flaky service can turn a half-second call into several seconds before it gives up. The attempts field is how you find out it happened.
Retries can repeat work. A timeout means we stopped waiting, not that the service stopped working, so a retried call may be processed twice. For a decision that only reads and answers, that’s harmless. It’s one more reason the function does no writing itself.
Validation isn’t perfect. It catches the shapes we know about. The API remains the authority and anything it rejects that we let through comes back as an http_4xx with its own explanation.
Going Further
We now have a function that fails gracefully and a set of claims about how: it retries these errors, doesn’t retry those, backs off by doubling and names each category. So far we’ve only shown the failures we can cause from Cypher. In the next chapter we test all of it properly, without a network and then add live notebooks as a second layer that checks the real thing.
Chapter 4: Testing Without a Network
The Problem with Testing a Network
Chapter 3 made a list of promises. The function retries a timeout but not a 422. It waits 500 milliseconds before the second attempt and 1,000 before the third. It reports “after 3 attempts” when it gives up. It never lets a bug escape as an exception.
We showed the promises that Cypher can trigger on demand, such as a bad option or a blank state. The rest are about the network and you can’t order up a network failure. A real timeout happens when it happens. A real 503 comes from a service having a bad day. If the only way to check the retry logic were to wait for those, we’d never know whether it worked until the day it mattered.
So we take the network out of the picture.
The Seam
We prepared for this in chapters 2 and 3, with two small interfaces.
HttpTransport is the only thing JevClient needs from the network. It takes a request and returns a status and a body, or throws an IOException. The real implementation, JdkHttpTransport, uses Java’s own HTTP client. The client never touches the network directly.
Sleeper is the only thing JevClient needs from the clock. The real one is Thread::sleep.
Each interface is a seam: a place where we can replace the real thing with one we control. Neither changes the code under test. The client behaves the same way whether it’s talking to Jev or to a stand-in.
A Scripted Transport
The stand-in is FakeTransport. You give it a script of outcomes. Each one is either a response to return or an IOException to throw. It plays them back in order and records every request it receives:
class FakeTransport implements HttpTransport {

    record Request(URI uri, Map<String, String> headers, String body,
                   Duration connect, Duration request) {}

    final List<Request> requests = new ArrayList<>();
    private final Deque<Object> outcomes = new ArrayDeque<>();
    private Object last;

    FakeTransport respond(int status, String body) {
        outcomes.add(new Response(status, body));
        return this;
    }

    FakeTransport fail(IOException e) {
        outcomes.add(e);
        return this;
    }

    @Override
    public Response post(URI uri, Map<String, String> headers, String body,
                         Duration connectTimeout, Duration requestTimeout) throws IOException {
        requests.add(new Request(uri, headers, body, connectTimeout, requestTimeout));
        Object next = outcomes.isEmpty() ? last : outcomes.poll();
        last = next;
        if (next instanceof IOException e) {
            throw e;
        }
        return (Response) next;
    }
}
When the script runs out, the last outcome repeats. That one rule makes a persistent failure easy to write. Queue a single 503 and every attempt gets a 503.
The recorded requests are the other half of the value. A test can check what was sent as well as what came back: how many attempts were made, what the headers were and what the body held.
For time, the test passes a different sleeper. Instead of sleeping, it adds the requested pause to a list:
@BeforeEach
void setUp() {
    transport = new FakeTransport();
    sleeps = new ArrayList<>();
    key = "test-key";
    client = new JevClient(transport, mapper, () -> key, sleeps::add);
}
The test runs instantly and sleeps holds exactly the waits the function asked for.
Testing Retries Without Waiting
Here’s the promise about a service that keeps failing, as a test:
@Test
void persistentServerErrorStopsAfterRetriesWithBackoff() {
    transport.respond(503, "unavailable");

    Map<String, Object> result = client.decide("x", questions(), Map.of());

    assertTrue(error(result).startsWith("http_5xx:"));
    assertTrue(error(result).contains("after 3 attempts"));
    assertEquals(3, transport.requests.size());
    assertEquals(List.of(500L, 1000L), sleeps);
    assertNull(result.get("answers"));
}
Read it as a list of the promises it checks. The category is http_5xx. The message says three attempts. The transport saw three requests. The waits were 500 and then 1,000 milliseconds. There are no answers. It’s the chapter 3 text, line by line and it finishes in a few milliseconds instead of the second and a half the real pauses would take.
A recovery is the other case worth checking. One 429, then a success:
@Test
void rateLimitThenSuccessRetriesOnce() {
    transport.respond(429, "slow down").respond(200, OK_BODY);

    Map<String, Object> result = client.decide("x", questions(), Map.of());

    assertNull(error(result));
    assertEquals(2L, metadata(result).get("attempts"));
    assertEquals(List.of(500L), sleeps);
}
The call succeeds, attempts says it took two and exactly one pause was requested.
Then the opposite, a failure that must not be retried:
@Test
void clientErrorIsNotRetried() {
    transport.respond(422, "bad criteria shape");

    Map<String, Object> result = client.decide("x", questions(), Map.of());

    assertTrue(error(result).startsWith("http_4xx: 422"));
    assertEquals(1, transport.requests.size());
    assertTrue(sleeps.isEmpty());
}
One request and no pauses. A test for what the function doesn’t do is as important as one for what it does, because it’s the kind of promise that breaks quietly when someone changes the retry rules later.
The other network tests follow the same pattern:
- A long error body is cut to 300 characters and ends with “…”.
- A timeout is retried, then reported with the
timeoutprefix. - Any other I/O failure is retried, then reported with the
ioprefix and the original message. - Setting
max_retriesto 0 means one attempt and “(after 1 attempt)”. - A 200 with a body that isn’t JSON becomes
malformed_response. - So does a 200 with JSON that has no
answers.
Testing What Never Reaches the Network
Some of the most important tests check that nothing was sent. The transport records every request, so “no call was made” is a plain assertion:
@Test
void missingKeyMakesNoCall() {
    key = null;

    Map<String, Object> result = client.decide("x", questions(), Map.of());

    assertTrue(error(result).startsWith("no_api_key:"));
    assertTrue(transport.requests.isEmpty());
}
The same check appears in the tests for invalid questions, invalid options, a null or blank state and a state of a type JSON can’t carry. This is how we know the validation from chapter 3 happens before the network, not after.
A few tests look at what was sent. One parses the request body and checks the model, the Authorization header and the shapes of the criteria: an object for a choice question and an array for a score question. Another feeds in a state map with keys b then a and checks the text sent is {"a":2,"b":1}. That’s the sorted-keys promise from chapter 2.
The remaining classes test the smaller parts on their own: OptionsTest for the option names, ranges and types, QuestionValidatorTest for the question shapes and TypeNormalizerTest for the conversions between Cypher’s types and JSON’s. They need no fake transport at all.
Maven runs all of them when you build. The build in code/04-testing-without-a-network ran 44 tests, 19 of them for the client, with no failures or errors:
Tests run: 11, Failures: 0, Errors: 0, Skipped: 0 -- QuestionValidatorTest
Tests run: 9,  Failures: 0, Errors: 0, Skipped: 0 -- TypeNormalizerTest
Tests run: 19, Failures: 0, Errors: 0, Skipped: 0 -- JevClientTest
Tests run: 5,  Failures: 0, Errors: 0, Skipped: 0 -- OptionsTest
Tests run: 44, Failures: 0, Errors: 0, Skipped: 0
The client’s 19 tests, including every retry and backoff case, took under a tenth of a second together, because nothing waits. A failing test would have stopped the build before it produced a JAR. That’s a useful property: the JAR you copy into plugins is one that passed its tests.
What the Tests Don’t Prove
A test against a fake proves one thing: the function does what we told it to do when the service behaves the way we told the fake to behave. It doesn’t prove that Jev behaves that way.
Suppose Jev changed how it reports an error, the response gained a new field or the real service rejected a request the fake would have accepted. The unit tests would stay green. The fake is only as honest as our understanding of the service.
That’s why there’s a second layer. It runs the real function in the real database, through Cypher, against the real service.
The Live Notebook
The notebook is notebooks/04_decide_tests.ipynb in the chapter’s folder. It connects to your database with the Python driver and runs one jev.decide call per test, the same way a query of yours would. Each test prints PASS or FAIL and, at the end, everything is saved to a file, results_decide.json, so a run can be kept and compared.
A few choices shape it:
- It never writes to the database. Every test is a read-only
RETURN. - It has four statuses. PASS and FAIL are checks with a clear right answer. INFO records something measured, such as a latency. SKIPPED means a test couldn’t run.
- The hosted section is off by default. A flag,
RUN_REAL_JEV, controls whether it makes real calls, so a plain run costs nothing. - A re-run replaces earlier results. Run a test cell again and its entry is updated, not duplicated.
This is the chapter 4 version. It tests what the function can do so far and later chapters add to it. The key rule joins in chapter 5 and the local model in chapter 7.
The first group of tests needs no key and makes no calls. It checks that the function is registered and that each kind of bad input produces a validation: error, no answers and zero attempts. That last part is how the notebook proves no request was made, without a fake. The function itself reports attempts: 0.
The second group is the optional one. With the flag on, it makes five real calls to Jev on one transaction and checks four things: no call returned an error, each took exactly one attempt, the choice is one we offered and the confidence equals the margin between the two probabilities. It allows a gap of 0.02 in that last check, because Jev rounds its probabilities to two decimals.
Reading the Results
Here’s the saved summary from a run with the flag on:
| Test | Status |
|---|---|
| function jev.decide is registered | PASS |
| validation: choice criteria as an array | PASS |
| validation: no call was made | PASS |
| validation: answers are null | PASS |
| validation: unknown option name | PASS |
| validation: blank state | PASS |
| validation: score criteria as a map | PASS |
| validation: retries out of range | PASS |
| validation: missing instructions | PASS |
| validation: no questions at all | PASS |
| real Jev: no errors | PASS |
| real Jev: one attempt each | PASS |
| real Jev: the choice is one we offered | PASS |
| real Jev: confidence is the margin between the two probabilities | PASS |
| real Jev: wall time per call (ms) | INFO |
Fourteen passes and one measurement. The detail column holds the error messages, which is a good way to see them all in one place. For example, the retries case reports validation: max_retries must be between 0 and 5 and the missing-instructions case reports validation: d: instructions are required.
The real-Jev check on confidence has a detail worth reading: confidence 0.04, margin 0.040000000000000036. The two agree up to the floating-point noise in the last digits. This transaction, a cash withdrawal at midnight far from home, is one of the ambiguous kinds from chapter 1 and a margin of 0.04 means Jev could barely separate Flag from Pass. The choice was Flag.
The measurement is the wall time per call: a minimum of 217 milliseconds, a median of 235 and a maximum of 550. The first of the five calls was the slowest. This number includes the trip over Bolt and the query planning, so it’s always a little more than the latency_ms the function reports about itself.
What You’d Hit in Production
A green suite can hide a bad fake. The unit tests check the function against our model of the service. The notebook is the check on that model. When the service changes, the notebook is the layer that notices.
Tests that wait are tests that get skipped. If the retry tests slept for real, each would take seconds and sooner or later someone would stop running them. The Sleeper seam is what keeps them fast enough to run every time.
The hosted section costs calls. The notebook only reads, but the hosted section spends real API calls. That’s why the flag defaults to off.
Run the notebook against the build you installed. The notebook tests whatever JAR is in the plugins folder. If you forget to swap in the new one and restart, it tests the old function.
Going Further
We now have a function that makes a decision, fails gracefully and has tests at two levels. There’s one problem left and it’s about the API key. The function sends it in a header and the moment we let the endpoint be configured, the address decides where the key goes. In the next chapter we look at how that can go wrong and the rule that stops it.
Chapter 5: Keeping the Key Safe
The Key’s Journey
Every call to Jev carries a secret: your API key, sent in an Authorization header. This chapter is about where that key lives, where it goes and how we made sure it can only go to one place.
Where it lives is simple. The function looks for TYPESAFE_API_KEY in an environment variable first and in a JVM property second. In chapter 2 we set it as a JVM option in the database’s settings, because Neo4j Desktop starts the database for you and a variable exported in a terminal may never reach it.
The key never appears in a Cypher query, so it never lands in your query log. It never appears in a result either. The notebook from chapter 4 never sees it and one of the unit tests checks that a failed call’s output doesn’t contain it.
Where it goes is the interesting part.
Why the Endpoint Must Be Configurable
Until now the function called one address, hard-wired in the code: Jev’s. That’s the safest possible design for a key, because there’s only one place it can go.
But chapter 7 uses the same function against a local model and that needs a different address. So the third argument gains a new option, url:
RETURN jev.decide($state, $questions, {url: 'http://localhost:11434/v1/systemone'})
The moment the address can change, the question of what to do with the key becomes a real one.
The Flaw
The obvious design for this option is to read the address from the options, send the request there and attach the key, as before.
We found the problem with that design while testing, before the option shipped. With it, the key goes wherever the caller points it. A typo sends it to the wrong place. A query built from untrusted input, such as a value read from a node property, could send it to an address someone else chose. Nothing was ever sent anywhere it shouldn’t have been. The flaw was in what the design allowed.
A credential should go to the service it belongs to and nowhere else. The code should enforce that rather than rely on every caller getting every address right.
The Tempting Fix
The first fix that comes to mind is to check the address as text. Send the key only if the URL starts with https://api.typesafe.ai. Or only if it contains api.typesafe.ai.
Both are fooled by addresses that look right and aren’t. Two examples:
https://api.typesafe.ai@evil.com/v1/systemone
https://api.typesafe.ai.evil.com/v1/systemone
The first one starts with exactly the right text. But in a URL, everything before an @ is a user name, so the host the connection goes to is evil.com. The second starts with the right text as well. It’s a subdomain of evil.com and whoever controls that domain controls where it points.
A check on the raw text can’t tell these apart from the real thing, because the text isn’t what the network connects to. The host is.
The Rule
So the rule works on the parsed address, not the text. The key is sent only if the scheme is https and the host is exactly api.typesafe.ai:
public boolean sendsApiKey() {
    return "https".equalsIgnoreCase(url.getScheme()) && KEY_HOST.equalsIgnoreCase(url.getHost());
}
Java’s own URL parser decides what the host is, the same way the HTTP client will when it connects, so there’s no gap between the check and the connection. For the two tricks above, the parser reports evil.com and api.typesafe.ai.evil.com. Neither equals api.typesafe.ai, so neither gets the key.
The rule is strict in other ways too. Plain http to the real host doesn’t get the key, because it would cross the network in the clear. Any other host, such as a local server, doesn’t either. The port isn’t part of the check, so https://api.typesafe.ai:8443/ is still the real host.
What happens to the request in the client follows from this one method:
boolean authenticated = options.sendsApiKey();
Map<String, String> headers = new LinkedHashMap<>();
headers.put("Content-Type", "application/json");
if (authenticated) {
    String key = apiKey.get();
    if (key == null || key.isBlank()) {
        return failure("no_api_key: set TYPESAFE_API_KEY as an environment variable or JVM property",
                model, started, 0, false);
    }
    headers.put("Authorization", "Bearer " + key);
}
There are two details here. First, the key is read inside the if. For any other endpoint the key supplier isn’t called at all, so the key doesn’t even pass through the code that builds that request. A test checks it by supplying a key function that throws if it’s called.
Second, a missing key is only an error for the real endpoint. A local model needs no key, so a call to one works on a machine where no key has ever been set.
Seeing It
The result now says what happened. A new field in the metadata, authenticated, tells you whether the key went out. Here’s a normal call to the real endpoint:
{
  answers: {
    decision: {
      type: "choice",
      choice: "Pass",
      probabilities: {
        Pass: 0.91,
        Flag: 0.09
      },
      confidence: 0.82
    }
  },
  error_message: null,
  metadata: {
    authenticated: TRUE,
    model: "jev-latest",
    latency_ms: 312,
    attempts: 1
  }
}
Now the same function pointed at another address. Nothing listens on port 9 of your own machine, so the connection is refused:
RETURN jev.decide(
  {amount: 120.5, merchant_category: 'grocery'},
  {decision: {
     type: 'choice',
     instructions: 'Should this transaction be flagged or passed?',
     criteria: {Flag: 'Potential fraud.', Pass: 'Likely legitimate.'}
  }},
  {url: 'http://127.0.0.1:9/v1/systemone', max_retries: 0}
) AS result
{
  answers: null,
  error_message: "io: ConnectException reaching 127.0.0.1:9 (after 1 attempt)",
  metadata: {
    authenticated: FALSE,
    model: "jev-latest",
    latency_ms: 0,
    attempts: 1
  }
}
The failure is reported as data, as in chapter 3. The message names the host and the port, so a wrong url is easy to spot and authenticated is false. That’s the rule at work. This address wasn’t the real Jev, so no key went with the request.
Leave max_retries at its default and the same call makes three attempts, with the pauses from chapter 3:
{
  answers: null,
  error_message: "io: ConnectException reaching 127.0.0.1:9 (after 3 attempts)",
  metadata: {
    authenticated: FALSE,
    model: "jev-latest",
    latency_ms: 1515,
    attempts: 3
  }
}
The call took 1,515 milliseconds, just over the 500 plus 1,000 milliseconds of waiting. That’s the backoff arithmetic from chapter 3 showing up in a real measurement.
The statements from this chapter are also in notebooks/05_key_demos.ipynb, which runs them one per cell and shows each result.
Errors That Name the Host
The error messages now name wherever the call was heading, not just the real host. Before this chapter an I/O failure always said api.typesafe.ai. Now it says the configured host and port, so with a local model a refused connection reads “reaching localhost:11434” and tells you at once that Ollama isn’t running.
The name is built from the parsed address too and it leaves out anything before an @. A URL such as https://user:secret@evil.com/x appears in an error as evil.com. Error messages end up in query results and logs and a password someone put in an address shouldn’t end up there with them.
Testing the Rule
The rule has to hold for every input, so it’s tested from both sides.
The unit tests check it directly. OptionsTest checks that the key is sent only to https://api.typesafe.ai and that case doesn’t matter. It checks that it’s never sent to localhost, to another site or over plain http and that the look-alike addresses don’t get it. Several tests in JevClientTest go further and look at the request the fake transport received. A local endpoint gets no Authorization header. The key isn’t sent to another host even when one is configured. An address with @evil.com is sent to evil.com and still without the key. The key function isn’t called for non-Jev endpoints. Together with the tests from earlier chapters there are now 55 and all of them passed.
The notebook, notebooks/05_decide_tests.ipynb in this chapter’s folder, checks it against the real function. It points jev.decide at two look-alike addresses. Both end in .invalid, a name reserved so that it never resolves, so the test sends nothing to a real server. One adds a suffix to the right name. The other puts the right name in front of an @. Both should come back with authenticated false and not with a no_api_key error.
Here’s what the notebook recorded:
| Test | Status | Detail |
|---|---|---|
| key rule: not sent to a look-alike (suffix on the real name) | PASS | |
| key rule: no key was needed (suffix on the real name) | PASS | |
| key rule: error text (suffix on the real name) | INFO | io: ConnectException reaching api.typesafe.ai.invalid (after 1 attempt) |
| key rule: not sent to a look-alike (real name as a user name) | PASS | |
| key rule: no key was needed (real name as a user name) | PASS | |
| key rule: error text (real name as a user name) | INFO | io: ConnectException reaching lookalike.invalid (after 1 attempt) |
The two INFO rows are the best evidence. For the address that starts with https://api.typesafe.ai@, the error says the function was reaching lookalike.invalid. That’s what the parser decided the host was and since it isn’t the real host, no key was sent. The text checks we rejected earlier would have sent it.
The rest of the run was clean as well. The notebook recorded 25 passes and 3 observations. That includes the closed-port checks, which show 1,516 ms for three attempts and the hosted section: five real calls, no errors, the key sent each time and one attempt each.
One more detail from that hosted run. The fixture is the midnight cash withdrawal from chapter 4 and this time Jev chose Pass, with confidence 0.08, margin 0.08000000000000002. In chapter 4 the same fixture gave Flag with a margin of 0.04. The transaction is a genuinely ambiguous one and Jev’s answers on it aren’t guaranteed to be the same from one run to the next.
What You’d Hit in Production
Point url at a service you trust and check what it’s for. The rule protects the Jev key. It doesn’t make every endpoint safe to call. A request to a local server or any other address still carries your transaction’s data, only without the key.
Notice authenticated: false. If you expect a call to go to Jev and see false, the address is wrong. It may be a typo, a trailing difference in the host or http instead of https.
A missing key shows up only for the real endpoint. A no_api_key error means the call was heading for Jev and the key wasn’t found. If you see it, check the environment variable and the JVM option, as in chapter 2.
Keys in neo4j.conf are still keys in a file. The JVM option keeps the key out of queries and results, but it sits in the database’s configuration. Treat that file like any other place a secret lives.
Going Further
The function now makes a decision, fails gracefully, has tests at two levels and sends its key to exactly one place. Everything so far works on one transaction at a time. The next chapter takes it to the whole graph: a batch procedure, a bounded thread pool and 500 decisions in one statement.
Chapter 6: Many at Once
One at a Time
Everything so far has been one decision per call. That’s fine for a single transaction, but our graph has 500 and a real one could have millions.
The problem is in how a function call works. jev.decide sends a request and waits for the answer and the whole query waits with it. A query that calls it for every node makes its calls one after another. From the chapter 4 notebook, a hosted call takes about a quarter of a second, so 500 of them in a row would take about two minutes. That’s an estimate from the arithmetic, but we’ll see later in this chapter that it holds up.
Most of that time is waiting. The database sits idle while Jev thinks. If we could have several requests in flight at once, the waiting would overlap. This chapter adds the piece that does it.
A Procedure, Not a Function
A function returns one value. What we want to return is a stream of rows, one per input, so the new piece is a procedure, jev.decideAll. Its shape is:
CALL jev.decideAll(items, questions [, options])
YIELD id, answers, error_message, metadata
The three arguments are:
itemsis a list of maps. Each has astate, which can be text, a map or a list as forjev.decideand usually anid. Without anid, the item’s position (0, 1, 2 and so on) is used.questionsis one map of questions, shared by every item.optionsis optional. It takes the same options asjev.decide, plus one new one:concurrency.
Each row it returns has the same answers, error_message and metadata as a single call, plus the id that was passed in. That lets us match each answer to its node.
Like jev.decide, the procedure is a thin wrapper. The class Neo4j sees, JevDecideAll, hands everything to BatchRunner, which holds the logic. BatchRunner takes the same JevClient we’ve been building, so every guarantee from the earlier chapters still applies to each row: validation first, retries with backoff, failures as data and the key rule.
A Bounded Pool
BatchRunner runs the calls on a pool of worker threads. The number of threads is the concurrency option, from 1 to 16 and it defaults to 4:
int threads = Math.min(concurrency, items.size());
ExecutorService pool = Executors.newFixedThreadPool(threads, runnable -> {
    Thread thread = new Thread(runnable, "jev-decide-" + THREAD_COUNTER.incrementAndGet());
    thread.setDaemon(true);
    return thread;
});
The pool is bounded for two reasons. The service has rate limits and a thousand simultaneous requests is a good way to meet them. And the database is serving other work, so a batch shouldn’t be able to take every thread it can find. The cap of 16 and the default of 4 are choices, not laws of nature and you can tune them for your own setup.
The threads are daemons and have names, jev-decide-1, jev-decide-2 and so on, so they’re easy to spot in a thread dump and can’t keep the database from shutting down.
One rule matters more than the others: the workers receive only plain values. They get a state, the questions and the options. They never touch the Neo4j transaction. The transaction belongs to the thread that called the procedure and handing it to other threads is a way to produce failures that are very hard to diagnose.
Order and Failures
The calls finish in any order, but the rows come back in the order the items were given. BatchRunner submits every item to the pool and then reads the results back by position:
for (int i = 0; i < items.size(); i++) {
    Object id = idOf(items.get(i), i);
    ...
    rows.add(futures.get(i).get());
}
Reading the first result waits for the first call, reading the second waits for the second and so on. A fast call that finished early simply waits its turn in the list. The caller sees the same order as the input.
A failing row doesn’t stop the others. Each row carries its own error_message, exactly as a single jev.decide call does. Beyond the failures JevClient already handles, the batch adds a few of its own:
- An item without a
state, or anullitem, becomes a row with avalidation:error. The rest run. - A bad
concurrencyvalue gives every row avalidation:error and makes no calls at all. - A batch holds at most 10,000 items. One more is rejected with a message that says so. Larger sets go in several calls.
- An unexpected exception in a worker becomes an
internal:error on its row.
If the thread that called the procedure is interrupted, for instance when someone cancels the query, the pool is shut down at once and the unfinished rows come back as interrupted: errors. The thread’s interrupt flag is set again afterwards, so Neo4j can see the cancellation.
Testing the Batch
The 12 new unit tests in BatchRunnerTest use the fake transport from chapter 4. They check the ordering, the bound on concurrency, the default of four, the per-row failures, the limits and the interrupt. All 67 tests in the project pass and the batch tests took about half a second, longer than the rest because they run real threads.
The notebook, 06_decideall_tests.ipynb, checks the same things against the real procedure. A closed port is enough for most of them, because every call fails and still has to land in the right row:
| Test | Status | Detail |
|---|---|---|
| order: one row per item | PASS | 20 rows |
| order: ids come back in input order | PASS | |
| concurrency 0 is rejected on every row | PASS | validation: concurrency must be between 1 and 16 |
| concurrency ‘two’ is rejected on every row | PASS | validation: concurrency must be a whole number |
| per-row: a missing state fails only that row | PASS | validation: item 0 needs a state |
| per-row: the next item still ran | PASS | io: ConnectException reaching 127.0.0.1:9 (after 1 attempt) |
| ids: a missing id falls back to the position | PASS | [0, 1] |
| limit: an empty list gives no rows | PASS | 0 rows |
The notebook recorded 20 passes and 2 measurements. The measurements come in the timing section below.
The Full Run
Now the whole graph. This statement picks every transaction without a decision, builds the list of items, calls jev.decideAll with a concurrency of 8 and stores each answer as a Decision node:
MATCH (t:Transaction)
WHERE NOT (t)-[:HAS_DECISION]->()
WITH collect({id: t.txn_id,
              state: t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
                        .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend}}) AS items
CALL jev.decideAll(
  items,
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {
       Flag: 'Potential fraud. Send for review.',
       Pass: 'Likely legitimate. Process normally.'
     }
  }},
  {concurrency: 8}
) YIELD id, answers, error_message, metadata
WITH id, answers, metadata, error_message
WHERE error_message IS NULL
MATCH (t:Transaction {txn_id: id})
MERGE (t)-[:HAS_DECISION]->(d:Decision)
SET d.choice     = answers.decision.choice,
    d.confidence = answers.decision.confidence,
    d.p_flag     = answers.decision.probabilities.Flag,
    d.p_pass     = answers.decision.probabilities.Pass,
    d.latency_ms = metadata.latency_ms,
    d.attempts   = metadata.attempts,
    d.model      = metadata.model
RETURN count(d) AS decisions_stored
The map projection is the same one we’ve used since chapter 2, so scenario, true_p and is_fraud never reach Jev. Three details are worth noting:
- Failed rows are left out. The
WHERE error_message IS NULLskips them, so a failure never produces a half-emptyDecision. - The statement can be run again. Its first line only picks up transactions that have no decision, so after a partial failure, running it a second time fills the gaps and leaves the rest alone.
MERGEon the relationship means it never creates a second decision for the same transaction. - It’s one call. The whole set of 500 goes to the procedure at once. The rows come back when every call has finished.
Neo4j reported:
Created 500 nodes, created 500 relationships, set 3,500 properties, added 500 labels

Completed after 15,465 ms
That’s 500 hosted decisions in about 15.5 seconds, around 31 milliseconds each. The sequential estimate at the start of the chapter, 500 calls at about a quarter of a second each, comes to about two minutes, so concurrency 8 took roughly an eighth of the time. The next section looks at why that fits.
The Decision node settles the properties we left open in chapter 1:
| Property | What it holds |
|---|---|
choice | Flag or Pass |
confidence | The margin between the two probabilities |
p_flag | The probability Jev gave to Flag |
p_pass | The probability Jev gave to Pass |
latency_ms | How long the call took, measured inside the function |
attempts | How many attempts it needed |
model | Which model answered |
What the Decisions Say
With the decisions stored, the questions from chapter 1 are queries. First, how the 500 split:
MATCH (:Transaction)-[:HAS_DECISION]->(d:Decision)
RETURN d.choice AS choice, count(*) AS n
ORDER BY n DESC
Jev flagged 268 transactions and passed 232. The query we promised in chapter 1 finds the flagged transactions it was least sure about:
MATCH (t:Transaction)-[:HAS_DECISION]->(d:Decision)
WHERE d.choice = 'Flag'
RETURN t.txn_id, t.amount, d.p_flag
ORDER BY d.p_flag ASC
LIMIT 5
╒════════╤════════╤════════╕
│t.txn_id│t.amount│d.p_flag│
╞════════╪════════╪════════╡
│"T0289" │187.76  │0.5     │
├────────┼────────┼────────┤
│"T0316" │161.26  │0.51    │
├────────┼────────┼────────┤
│"T0359" │242.68  │0.51    │
├────────┼────────┼────────┤
│"T0361" │226.94  │0.51    │
├────────┼────────┼────────┤
│"T0431" │350.45  │0.51    │
└────────┴────────┴────────┘
These are the closest to a coin flip and a reviewer should look there first. Now we can use the hidden label, which Jev never saw:
MATCH (t:Transaction)-[:HAS_DECISION]->(d:Decision)
RETURN d.choice AS choice, t.is_fraud AS is_fraud, count(*) AS n
ORDER BY choice, is_fraud
| Decision | Not fraud | Fraud |
|---|---|---|
| Flag | 97 | 171 |
| Pass | 214 | 18 |
Of the 189 transactions labeled as fraud, 171 were flagged and 18 were passed. Of the 268 flagged, 97 were legitimate. Those 18 are the cases to worry about, so a query can list them, least sure first:
MATCH (t:Transaction)-[:HAS_DECISION]->(d:Decision)
WHERE d.choice = 'Pass' AND t.is_fraud = 1
RETURN t.txn_id, t.scenario, d.p_flag
ORDER BY d.p_flag DESC
LIMIT 5
╒════════╤══════════════╤════════╕
│t.txn_id│t.scenario    │d.p_flag│
╞════════╪══════════════╪════════╡
│"T0441" │"night_atm"   │0.49    │
├────────┼──────────────┼────────┤
│"T0089" │"night_atm"   │0.45    │
├────────┼──────────────┼────────┤
│"T0180" │"big_purchase"│0.32    │
├────────┼──────────────┼────────┤
│"T0357" │"big_purchase"│0.26    │
├────────┼──────────────┼────────┤
│"T0113" │"big_purchase"│0.26    │
└────────┴──────────────┴────────┘
The scenario column shows where the misses come from: late-night cash withdrawals and big purchases, the kinds of transaction that chapter 1 described as genuinely ambiguous. Remember that the labels were drawn from a latent probability, so some “fraud” here is fraud that no judge could be sure of.
The last of the questions from chapter 1 is how much of the graph could be handled without a person looking at it. That depends on a threshold and any number we pick is an illustration:
MATCH (:Transaction)-[:HAS_DECISION]->(d:Decision)
RETURN count(*) AS decisions,
       sum(CASE WHEN d.confidence >= 0.8 THEN 1 ELSE 0 END) AS confident,
       round(100.0 * sum(CASE WHEN d.confidence >= 0.8 THEN 1 ELSE 0 END) / count(*), 1) AS percent_confident
With a confidence of 0.8 as the line, 254 of the 500 decisions, or 50.8%, were confident.
The Same Run Twice
We ran the whole batch twice. The first run’s decisions were deleted before the second and everything above comes from the second. Here are the two side by side:
| First run | Second run | |
|---|---|---|
| Flagged | 267 | 268 |
| Passed | 233 | 232 |
| Flagged, not fraud | 96 | 97 |
| Passed, fraud | 18 | 18 |
| Confident (0.8 or more) | 246 | 254 |
To run the batch again from scratch, delete only the decisions and leave the transactions alone:
MATCH (d:Decision) DETACH DELETE d
The full-run statement only picks up transactions that have no decision, so without this step a second run would find nothing to do.
All nine statements from this chapter are also in notebooks/06_run_all_500.ipynb, which runs them one per cell and shows each result. The reset is the last one and is switched off by default. If the decisions are already stored, statement 2 stores 0, because it only picks up transactions that have no decision yet.
The overall picture is stable and the details move. A transaction at the edge can land on either side and the five least-sure flags were completely different transactions each time (T0467, T0476 and T0020 led the first run’s list, T0289, T0316 and T0359 the second’s). All of them sat at 0.50 or 0.51. The transactions near the line move around and the ones far from it don’t.
That has a practical consequence. If you store decisions, treat them as a snapshot from one run of a service that can answer slightly differently the next time. The model and latency_ms properties on each Decision help you tell runs apart later.
What the Timings Show
The notebook’s hosted sweep times a batch of 20 items at four levels of concurrency, twice each. The batches are taken in rotation so a slow stretch on the network doesn’t land on one level.
| Concurrency | Run 1 (ms) | Run 2 (ms) | Median (ms) | Speedup |
|---|---|---|---|---|
| 1 | 5,118 | 4,438 | 4,778 | 1.0x |
| 4 | 1,212 | 1,121 | 1,167 | 4.09x |
| 8 | 703 | 693 | 698 | 6.85x |
| 16 | 828 | 463 | 646 | 7.4x |
There were no errors at any level. At a concurrency of 1, the 20 calls took about 240 milliseconds each, which gives us the number behind the estimate at the start of the chapter. The speedup is close to the concurrency at 4 and a little under it at 8, so most of the time really was waiting.
The result at 16 needs a note. Twenty items on 16 workers still need two rounds, because the last four calls have to wait for workers to free up. If every call took the same time, the best possible speedup would be 10 times and the measured 7.4 falls short of that. Calls vary in length and the second round waits for its slowest call, but we didn’t measure how much of the gap that explains. More workers than items buys nothing, because a batch of 20 can’t use 32 threads.
Back to the full run: 500 calls at about 240 milliseconds would take roughly 120 seconds one at a time. The measured 15.5 seconds at a concurrency of 8 is about 7.7 times faster, which is in line with the roughly 7 times the sweep showed at that level. The full run wasn’t repeated, so treat that as one measurement and not a benchmark.
What You’d Hit in Production
More concurrency only helps if the service can answer in parallel. A hosted API usually can, as the sweep shows. Chapter 7 puts a local model behind the same procedure and the picture is different.
Retries aren’t coordinated. A 429 on one row is retried with the same backoff as in chapter 3, but the rows don’t share a throttle. At a high concurrency a rate-limited service can see many retries at once.
Rows arrive when everything is done. The procedure returns once every call has finished, so a large batch against a slow endpoint takes that long before the first row appears. Keep batches to a size you’re happy to wait for.
Batches have a ceiling. At 10,000 items per call, a bigger graph goes in slices. The “no decision yet” filter in the full run makes that easy, because each pass picks up where the last stopped.
Decisions are data you now own. The stored Decision nodes don’t change when the service does. If you want fresh ones, delete the old Decision nodes first, as we did for the second run.
Going Further
We’ve gone from one decision to a stored, queryable judgment on every transaction, with timings that show the pool earning its place. In the last chapter we swap the service behind the same function. The hosted model gives way to a small one running on your own machine and we’ll see what stays the same, what changes and what that does to the numbers.
Chapter 7: Running It Locally
Why Run Locally
Every decision so far has gone out over the internet. For some graphs that’s fine. For others it isn’t: the data may not be allowed to leave the building, the calls may add up to a cost you’d rather avoid or the machine may simply be offline.
A local model answers those objections. The data stay on your computer, no key is needed and nothing is sent anywhere. The price is what you’d expect: a small model on a laptop is not the same thing as a large hosted service and this chapter measures the difference instead of assuming it.
We use Ollama to serve the model. It exposes the same request format that Jev’s API speaks, so the function we’ve built needs no new code. Everything in this chapter uses options we already have: model from chapter 2, url from chapter 5 and concurrency from chapter 6.
Same Function, New Address
Pull the model once:
ollama pull tev1:0.8b
Then call jev.decide as before, with two options: the address of the local server and the name of the model:
MATCH (t:Transaction {txn_id: 'T0001'})
RETURN jev.decide(
  t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
     .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend},
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {
       Flag: 'Potential fraud. Send for review.',
       Pass: 'Likely legitimate. Process normally.'
     }
  }},
  {url: 'http://localhost:11434/v1/systemone', model: 'tev1:0.8b'}
) AS result
This is what came back:
{
  answers: {
    decision: {
      type: "choice",
      choice: "Pass",
      probabilities: {
        Pass: 0.7310585786300049,
        Flag: 0.2689414213699951
      },
      confidence: 0.16005846201683083
    }
  },
  error_message: null,
  metadata: {
    authenticated: FALSE,
    model: "tev1:0.8b",
    latency_ms: 961,
    attempts: 1
  }
}
The shape is the one we know. The choice is Pass, the probabilities add up to 1 and the metadata names the model that answered.
Look at authenticated. It’s false, which is the rule from chapter 5 at work. The key is sent only to Jev, so a call to your own machine goes out without it. You don’t need a key on a machine that only ever talks to a local model and a missing key is not an error here.
One new unit test checks that a response from a local server, with extra fields in it, is accepted. That brings the suite to 68 tests.
Same Shape, Different Meaning
The result looks the same, but one field means something else. In chapter 2 we saw that Jev’s confidence is the margin between the two probabilities. The local server’s confidence is one minus the normalized entropy of the probabilities, a different measure.
For the answer above, the probabilities are 0.731 and 0.269. The margin between them is 0.462. The reported confidence is 0.160. Both are reasonable numbers for the same answer and neither is wrong. They just aren’t the same thing, so a Cypher query that compares confidence across the two sources would be comparing different quantities.
The notebook tests this directly. For the one transaction it uses, it checks that the reported value is one minus the normalized entropy and that it is not the margin:
| Test | Status | Detail |
|---|---|---|
| local model: confidence is one minus normalized entropy | PASS | |
| local model: confidence is NOT the margin that Jev reports | PASS | reported 0.0112, margin 0.1244 |
The fix is to compute the margin yourself from the probabilities, which both sources provide. In Cypher it’s one expression:
abs(d.p_flag - d.p_pass) AS margin
The local decisions we store later in this chapter carry a margin property for exactly this reason.
There’s one smaller difference. A score question can come back from the local model as an integer, such as 1, where Jev can return a float, such as 1.25. The notebook records the type as int. If you do arithmetic on scores from both sources, use toFloat() first.
Cold and Warm
The first call to a local model is slow, because the server has to load the model into memory. Later calls find it already loaded. The notebook measures both by asking the server to unload the model, making one call and then ten more.
The cold call took 574 milliseconds. The ten warm calls took between 16 and 21 milliseconds, with a median of 17. Inside the function the cold call took 565 milliseconds and the warm ones between 11 and 14. The median overhead of the trip over Bolt and the Cypher planning was 6 milliseconds.
So a warm local call, measured this way, is far faster than a hosted call, which took around 235 milliseconds in chapter 4. But keep reading, because a warm call on a repeated request turns out not to be the whole story.
Failures Are Still Data
Everything from chapter 3 carries over, because the local server goes through the same JevClient. Two cases show it.
Ask for a model that hasn’t been pulled and the server answers with a 404. The function reports it as a client error and doesn’t retry, because retrying a missing model can’t help:
http_4xx: 404 {"error":"model \"does-not-exist\" not found, try pulling it first"}
The notebook confirms the call used one attempt. Run the same request as a batch and every row reports the same error and the batch still finishes.
If the server isn’t running at all, the connection is refused. The error names the host and the port, localhost:11434, so you can tell at once that it’s the local server that’s missing and not the network. It’s an io error, so it’s retried with the usual backoff before the function gives up.
Repeatable, in Steps
Run the same call three times and the hosted service may answer with slightly different probabilities each time, as we saw in chapters 5 and 6. The local model doesn’t. In the notebook, three identical calls gave exactly one distinct result and a row from jev.decideAll was identical to the same state sent through jev.decide.
Repeatable doesn’t mean fine-grained. Across all 500 local decisions in the full run below, p_flag took only 16 distinct values. Ten of them covered 428 of the 500 decisions and the three most common, 0.2227, 0.2451 and 0.2689, covered 184. Every one of the 16 is the logistic function of a multiple of 0.125. For example, 0.2689 is 1/(1+e^1), 0.2227 is 1/(1+e^1.25) and 0.5 is 1/(1+e^0). We don’t know why the model answers in steps like these and we haven’t tried to find out. What matters in practice is that many transactions get exactly the same probability, so there’s less room to rank them by how sure the model was.
The Full Run, Locally
Now the same 500 transactions. The statement is the one from chapter 6, with two changes: the options point at the local server and the answers are stored as LocalDecision nodes, linked by HAS_LOCAL_DECISION. That leaves the hosted Decision nodes untouched, so the two sets can be compared:
MATCH (t:Transaction)
WHERE NOT (t)-[:HAS_LOCAL_DECISION]->()
WITH collect({id: t.txn_id,
              state: t {.amount, .merchant_category, .distance_from_home_km, .hour_of_day,
                        .account_age_days, .prior_flags, .txns_last_24h, .typical_monthly_spend}}) AS items
CALL jev.decideAll(
  items,
  {decision: {
     type: 'choice',
     instructions: 'Based on all available signals, should this transaction be flagged for review or passed through?',
     criteria: {
       Flag: 'Potential fraud. Send for review.',
       Pass: 'Likely legitimate. Process normally.'
     }
  }},
  {url: 'http://localhost:11434/v1/systemone', model: 'tev1:0.8b', concurrency: 4}
) YIELD id, answers, error_message, metadata
WITH id, answers, metadata, error_message
WHERE error_message IS NULL
MATCH (t:Transaction {txn_id: id})
MERGE (t)-[:HAS_LOCAL_DECISION]->(l:LocalDecision)
SET l.choice     = answers.decision.choice,
    l.confidence = answers.decision.confidence,
    l.p_flag     = answers.decision.probabilities.Flag,
    l.p_pass     = answers.decision.probabilities.Pass,
    l.margin     = abs(answers.decision.probabilities.Flag - answers.decision.probabilities.Pass),
    l.latency_ms = metadata.latency_ms,
    l.attempts   = metadata.attempts,
    l.model      = metadata.model
RETURN count(l) AS local_decisions_stored
Neo4j reported:
Created 500 nodes, created 500 relationships, set 4,000 properties, added 500 labels

Completed after 44,843 ms
Five hundred local decisions, all stored, in about 45 seconds at a concurrency of 4. The hosted run took 15.5 seconds at a concurrency of 8. These two aren’t a like-for-like comparison, since the concurrency differs and we’ll come back to what the local server does with parallel calls.
The function’s own latency averaged 349 milliseconds per call locally and 243 hosted. The local calls ranged from 124 to 742 milliseconds, with a median of 332.5.
Hosted Against Local
The queries now have two sets of decisions to compare. First, what the local model decided, set against the hidden label:
| Local decision | Not fraud | Fraud |
|---|---|---|
| Flag | 4 | 16 |
| Pass | 307 | 173 |
The local model flagged 20 transactions and passed 480. Of the 189 transactions labeled as fraud, it flagged 16 and passed 173. For comparison, the hosted run in chapter 6 flagged 171 of those 189 and passed 18.
Then the two sets against each other:
| Hosted | Local | Transactions |
|---|---|---|
| Flag | Flag | 20 |
| Flag | Pass | 248 |
| Pass | Pass | 232 |
They agree on 252 of the 500 and the local model never flagged anything the hosted service passed. The 248 disagreements aren’t confined to the ambiguous cases. By scenario:
| Scenario | Disagreements |
|---|---|
| card_testing | 64 |
| clear_fraud | 54 |
| night_atm | 51 |
| traveler | 47 |
| takeover | 31 |
| big_purchase | 1 |
We ran the full local run twice. Every total matched, but the scenario counts differed by one transaction between night_atm and takeover, so treat a count at that level with care.
The scenario list includes clear_fraud, where we’d expect any judge to flag. This small model, with the same prompt and the same eight properties, is simply far more willing to pass. When it flags, it’s usually right (16 of its 20 flags were fraud), but it flags very few.
That doesn’t make the local model useless. It means that with this prompt it’s a conservative filter and anyone using it would want to look at its confidence and the instructions again before trusting it with the same job. We haven’t tried other prompts or other models, so we can’t say whether a different setup would close the gap.
The confidence scales show the earlier point in numbers. Averaged over the 500 transactions, the hosted service’s reported confidence was 0.693 and its margin, computed from the probabilities, was also 0.693, because for Jev they’re the same thing. The local model’s reported confidence averaged 0.122, but its margin averaged 0.356. The reported numbers differ by a factor of almost six and the margins by a factor of two. Only the margin puts them on one scale.
The statements from this chapter are also in notebooks/07_run_local_500.ipynb, which runs them one per cell and shows each result. The last one deletes the local decisions and is switched off by default.
Concurrency Locally
In chapter 6 the pool gave a speedup close to the number of workers, because the hosted service could answer many requests at once. A model on one laptop is a different matter, since all the calls share the same hardware.
The notebook’s local sweep times a batch of 40 items at five levels of concurrency, ten times each, with a warm-up batch at every level first. The medians:
| Concurrency | Median (ms) | Speedup |
|---|---|---|
| 1 | 405 | 1.0x |
| 2 | 185 | 2.19x |
| 4 | 188 | 2.15x |
| 8 | 263 | 1.54x |
| 16 | 181 | 2.24x |
There were no errors at any level. A second worker roughly halves the time, a speedup of about 2.2 times and more workers add nothing reliable. At 4 the median matched 2, at 8 it was slower and at 16 it was back near 2. That’s not the hosted result, where the speedup kept growing. A local model can run only so many calls at once and extra workers just queue behind each other. The sweep doesn’t show that 4 workers beat 2, which is worth remembering since we used 4 for the full run.
The individual timings show something else, which we can’t yet explain. At concurrency 4 the ten runs of the same batch fell into two groups. Seven took 174 to 196 milliseconds and three took 307 to 353. At concurrency 2 the runs split in a similar way: seven took 162 to 196 and three took 286 to 351. At 16 six took 163 to 182 and four took 295 to 363. At 8 the pattern is looser, with all but two runs between 258 and 350. The slow group is roughly twice the fast one and which runs landed in which group looks random. At a concurrency of 1 every run took between 308 and 593 milliseconds, with no fast group.
We don’t know why. It could be the model server, the machine or the way the calls overlap and we haven’t separated these. We report it because it affects how far to trust a single timing and because the same batch taking either of two speeds is the kind of thing that would ruin a benchmark that ran each setting once.
There’s a bigger caveat on the sweep itself. It sends the same 40 requests again and again, with only four properties in each state. At 4 workers the median batch of 40 took 188 milliseconds, about 5 milliseconds per item. The full run sent 500 different transactions, each with eight properties and took about 90 milliseconds per item at the same concurrency. That’s about twenty times slower per item. We haven’t tested whether repetition, the size of the state or something else explains it. The sweep shows how the speedup changes with concurrency. It doesn’t tell you what a real run costs and for that you need to run the real thing, as we did above.
What You’d Hit in Production
Check the model is pulled before a batch. A missing model fails every row with the same 404. It fails fast and clearly, but you still lose the run.
Time the real run, not a repeated request. A request that repeats is much cheaper than a stream of new ones. Warm calls of 16 to 21 milliseconds describe the best case and not what your graph will cost.
Don’t expect more workers to help a local model. More workers kept helping hosted calls, but a local model gained little beyond the second one. Measure on your own hardware before raising it.
Don’t compare reported confidence across the two sources. Compute a margin from the probabilities. That’s what the margin property on LocalDecision is for.
A model and a prompt are a pair. Our local model flagged very little with the same prompt that made the hosted service flag more than half. Treat a change of model like a change of judge and test it against labels you trust before using its decisions.
Local doesn’t mean unmanaged. The model server runs on your machine, uses its memory and can be stopped or updated by you. If it isn’t running, calls fail with an io error that names it.
Where We’ve Got To
We started with a graph that couldn’t answer a question about judgment. We now have a function that makes one decision, a procedure that makes thousands, errors that come back as data, tests that need no network, a key that can only go to one place and a choice of where the model runs. Each lesson came from something that went wrong or something we measured and each is in the code and the numbers in this book.
Conclusions
What We Built
We started with a graph that could answer questions about structure and none about judgment. We ended with this:
- A function,
jev.decide, that takes a node’s properties and some questions and returns an answer with probabilities, from Cypher. - A procedure,
jev.decideAll, that does the same for many nodes at once, on a bounded pool, with results in input order. - A suite of 68 tests that need no network and two notebooks that check the real thing.
- 500 stored decisions from a hosted service and 500 from a local model, as nodes linked to the transactions they describe, ready to query.
Each chapter contributed one lesson:
| Chapter | The lesson |
|---|---|
| 2. A First Working Function | Neo4j’s types stop at the boundary, so convert them on the way in and out. |
| 3. Failures as Data | A call that can fail should return its failure as a value, so one bad node can’t stop a query. |
| 4. Testing Without a Network | Put a seam where the network and the clock meet and the hard cases become fast tests. |
| 5. Keeping the Key Safe | A credential goes to the host the parser reports, not the one the text suggests. |
| 6. Many at Once | Concurrency has to be bounded, ordered and measured. |
| 7. Running It Locally | Swapping the model is cheap, but it changes the judgment and not just the speed. |
What the Lessons Share
Look back over the six and a pattern shows. Each one moves a decision out of a place where it would be made by accident and into a place where it’s made on purpose.
The type rules decide what crosses the boundary instead of letting a stray Integer through. The error prefixes decide what a failure looks like instead of leaving it to whatever exception arrives. The seams decide what a test controls. The host rule decides where the key goes, so no caller has to get that right every time. The pool decides how much runs at once. And the options decide which model answers.
None of these is clever. Each is a small piece of structure put where a mistake would otherwise be easy and most were added because we’d hit the problem or seen it coming while testing.
What the Numbers Did and Didn’t Show
We measured a fair amount and it’s worth being plain about what it supports.
The hosted service is close to repeatable, not exactly. We ran the full set of 500 twice. The totals barely moved, 267 flags in the first run and 268 in the second, but the five least-sure flags were different transactions each time, all at 0.50 or 0.51. The transactions near the line move around and the ones far from it don’t. If you store decisions, treat them as a snapshot.
Concurrency paid off against the hosted service. In the sweep of 20 items, 4 workers gave 4.09 times the speed of 1, 8 gave 6.85 times and 16 gave 7.4 times. The full run of 500 took 15,465 milliseconds at a concurrency of 8, where one at a time would have taken about two minutes by our estimate. Against the local model the picture was different: two workers gave about 2.2 times and more workers added nothing reliable.
A small local model is a different judge. With the same prompt and the same eight properties, the small local model (tev1:0.8b, served by Ollama) flagged 20 of the 500 and caught 16 of the 189 transactions labeled as fraud, where the hosted service flagged 268 and caught 171. The two agreed on 252 of 500. We haven’t tried other prompts or models, so this shows how far apart the two setups are with this one prompt. It doesn’t say what a local model can do. Its probabilities also came in only 16 distinct values, which we noted and didn’t explain.
Timings from a repeated request mislead. The local sweep sent the same 40 small requests again and again and ran at about 5 milliseconds per item. The full run, with 500 different transactions, ran at about 90 milliseconds per item at the same concurrency. We haven’t found out why and it’s a reminder to time the real workload.
One thing we can’t explain. At several levels of local concurrency, the same batch took one of two speeds, one about twice the other, with no pattern we could see.
The data are synthetic. Each transaction was generated from a scenario with a latent probability of fraud and the label was drawn from it, so some of the fraud in the data was never certain. The results say how the code and the models behave on this data. They aren’t evidence about real fraud.
What We Left Out
A few things the build doesn’t do, which you’d want to think about before relying on it:
- There’s no caching. The same state sent twice makes two calls.
- Retries aren’t coordinated. A rate limit on one call is retried with the same backoff as in a single call and the calls in a batch don’t share a throttle.
- A batch returns when it’s finished. The procedure sends its results when every call is done, so a large batch against a slow endpoint takes that long before anything comes back.
- A batch has a ceiling. Each call takes at most 10,000 items and a bigger graph goes in slices.
- It needs Neo4j Desktop. Custom plugins aren’t available on Aura.
- We tried one prompt and two models. The hosted service and
tev1:0.8bthrough Ollama, with the setup in chapter 7. Better instructions or a different model might do much better and we didn’t look.
Where to Go Next
Because the pieces are small, there are several ways to take this further without rewriting any of it.
Try other models and prompts. The url and model options are the only things that change. Run a new model over the 500 transactions, store the answers beside the others and use the queries from chapter 7 to compare them.
Use the confidence to decide who looks. The stored probabilities give you a margin, the gap between p_flag and p_pass. A small margin marks a decision that deserves a person’s eyes. Where to draw the line is yours to choose and the 0.8 in chapter 6 was only an illustration.
Ask more than one question. We used a single choice question. The function also takes score questions and its validator checks both shapes before any call is made.
Keep the habits. Even if you never use this function, the habits in these chapters apply to any custom code that calls out of Neo4j: return failures as values, put a seam where the outside world meets your code, decide in code where a credential can go and measure the real workload.
A Last Word
Putting a model call inside a database turned out to be less about the model than about everything around it: the types, the failures, the key, the tests and the numbers. The decision is one line of Cypher. What makes that line safe to run over a whole graph is the rest of the book.
Free Books
The SingleStore Cookbook: Recipes for Multi-Model, Machine Learning and AI Data Engineering
A hands-on cookbook covering SingleStore’s multi-model capabilities, from time series and geospatial data through vector search, machine learning pipelines and AI-powered applications. The recipes draw on first-hand experience building applications with the platform and are organized into four parts:
- Multi-Model
- Streaming and Big Data Pipelines
- Machine Learning
- AI and Agentic Frameworks
Seven Vector Databases in Seven Days
A practical guide that takes one vector database per day and pairs each with a use case chosen to showcase that database’s strengths. Databases covered:
- PostgreSQL and pgvector - Semantic job search
- MongoDB Atlas - Recipe finder
- Pinecone - E-commerce search
- Weaviate - Research paper discovery
- Neo4j - Fraud detection
- Snowflake - Customer support analytics
- Databricks - RAG over internal documents
Each chapter is self-contained, comes with a Jupyter notebook and gives an assessment of when you’d look elsewhere.
Generative AI: A Manager’s Guide
A practical guide for managers, directors and executives who need to make decisions about AI in their organizations, not the engineers building it, but the people responsible for making it work well. The book uses a single central metaphor, the Digital Intern, to frame what AI is genuinely good at, where it falls short and what managing it actually requires. It covers governance, risk, board-level accountability, business case building and the organizational change of moving from pilot to embedded capability.
Seven Ways to Do Vector Search in Python
A practitioner’s guide that benchmarks seven Python libraries against the same dataset, measuring recall and latency consistently so you can compare like-for-like. Libraries covered:
- FAISS
- Voyager
- Scikit-learn NearestNeighbors
- PyNNDescent
- USearch
- Chroma
- LanceDB
Each chapter covers one library, explains what it’s genuinely good at and when you’d reach for something else.
Real-Time Vehicle Tracking with Neo4j, Databricks Lakebase and OpenStreetMap
A fleet operations demo that puts ten simulated vehicles onto real road networks loaded from OpenStreetMap. The architecture:
- Neo4j Aura holds the road network graph
- Databricks Lakebase stores live vehicle positions
- Databricks Lakehouse handles historical analytics
Two Streamlit dashboards display live positions and trend data. The primary demo uses the London Borough of Merton, with additional configurations for San Francisco and Singapore.
Real-Time Supply Chain Routing with Neo4j, Snowflake Postgres and Confluent Kafka
A supply chain routing demo that combines graph-based route optimization with real-time event streaming. The architecture:
- Neo4j Aura holds the supplier and logistics network graph
- Snowflake Postgres stores product and inventory data
- Confluent Kafka streams supply chain events in real time
Route queries traverse the graph to find optimal paths between suppliers, warehouses and distribution centers under live capacity and disruption constraints.
Neo4j Beyond the Graph
A hands-on guide to Neo4j’s multi-model capabilities, going beyond graph traversal to explore seven native features of the platform. Each chapter pairs one capability with a use case chosen to showcase it:
- Native Graph - London Underground routing
- Full-Text Search - Research paper discovery
- Geospatial - Air quality along the Pyrenees corridor
- Temporal - S&P 500 stock price analysis
- Document-Style Properties - Library inventory management
- Vector Search - Fashion image similarity
- Graph + Vector - Fraud ring detection
Every chapter comes with a Jupyter notebook and a Streamlit application. All examples run on Neo4j Aura’s free tier.
Seven Ways to Use Jev
A practical guide to TypeSafe AI’s structured decision model, exploring seven domains where a single Choice call – structured state in, typed decision out, calibrated confidence alongside – replaces brittle rules-based logic. Each chapter pairs one domain with a hands-on Jupyter notebook and examines what the confidence score reveals about the decision:
- Transit Routing - Northern Line branch triage using a NetworkX graph
- Customer Support Triage - Ticket routing by team and priority
- Financial Fraud Detection - Flag or pass with a three-tier confidence response
- Content Moderation - Approve, flag or remove user-generated content
- Supply Chain Disruption - Alternative supplier selection under live constraints
- Hiring Screening - CV screening against a structured job description
- Medical Symptom Triage - Care pathway assignment with a conservative bias
A recurring theme across all seven chapters: the confidence score is more informative than the decision itself for uncertain cases and the threshold between automatic routing and human review is always a business decision, not a technical one.
Lessons Learned Putting Jev Inside Neo4j
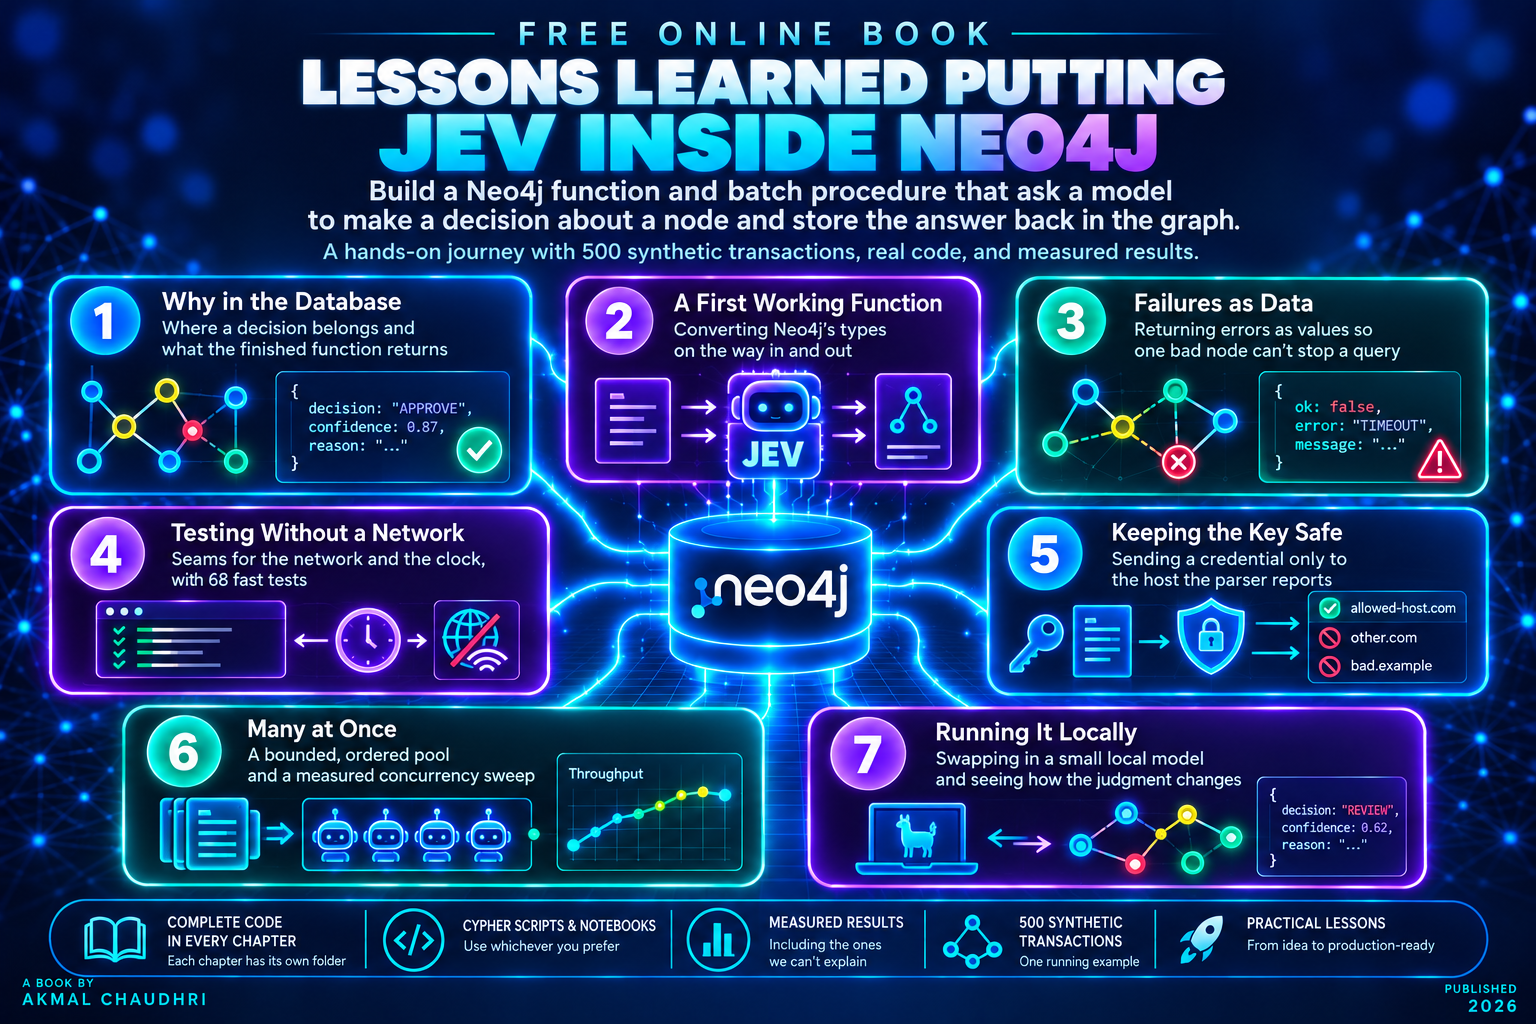
A hands-on account of building a Neo4j function and batch procedure in Java that ask a model to make a decision about a node and store the answer back in the graph. The book follows one running example, 500 synthetic transactions and each chapter adds the code that the previous chapter’s problem called for. The lessons:
- Why in the Database - Where a decision belongs and what the finished function returns
- A First Working Function - Converting Neo4j’s types on the way in and out
- Failures as Data - Returning errors as values so one bad node can’t stop a query
- Testing Without a Network - Seams for the network and the clock, with 68 fast tests
- Keeping the Key Safe - Sending a credential only to the host the parser reports
- Many at Once - A bounded, ordered pool and a measured concurrency sweep
- Running It Locally - Swapping in a small local model and seeing how the judgment changes
Every chapter with code has its own folder in the repository and each Cypher script also comes as a notebook, so you can use whichever you prefer. The results are reported as measured, including the ones we can’t explain!